A modern data warehouse can solve one problem and quietly create another.
The organization finally has consolidated data, standardized pipelines, and trusted reporting logic. Then demand explodes. Finance wants a new margin view. Sales wants pipeline by segment. Marketing wants campaign cohorts. Operations wants exceptions by location. Executives want a different cut of the same KPI before tomorrow’s meeting.
If every question still requires a ticket to the BI team, the warehouse has centralized data without decentralizing access to insight. The result is a reporting bottleneck: a small group of analysts becomes the interface between the business and its own data.
Self-service analytics is the attempt to remove that bottleneck. But it is often misunderstood. It does not mean giving everyone unrestricted access to raw tables or expecting business users to become data engineers. Effective self-service means enabling people to answer an appropriate class of questions independently while keeping definitions, security, quality, and accountability under control.
For executives, the objective is not maximum analytical freedom. It is faster decision-making without sacrificing trust.
What self-service analytics actually means
A useful self-service model has three characteristics.
First, users can explore trusted data without waiting for a specialist to build every report. Second, common business concepts such as revenue, active customer, qualified opportunity, gross margin, and churn have controlled definitions. Third, access to data reflects the user’s role and legitimate business need.
This is fundamentally different from simply buying more BI licenses.
Tools can make exploration easier, but the real foundation is the combination of data engineering, semantic modeling, governance, security, and user enablement. Actiknow’s Business Intelligence services, for example, cover dashboard development, BI implementation and consulting, integration with databases and APIs, data analysis and modeling, and automation. Those are the kinds of capabilities that sit underneath a sustainable self-service environment.
Why the reporting bottleneck appears
Most reporting bottlenecks are not caused by a lack of dashboards. They emerge because the organization has concentrated too many responsibilities in one team.
The central BI team may be expected to understand every source system, resolve data-quality problems, interpret every business definition, write transformations, create dashboards, manage permissions, answer ad hoc questions, and support users. As adoption grows, demand grows faster than the team’s capacity.
The queue then becomes self-reinforcing. Business users ask for more static reports because they cannot explore safely themselves. Analysts spend more time servicing repetitive requests and less time improving the data model. Documentation falls behind. Users trust the BI team but not necessarily the underlying data. Every new question returns to the same queue.
A warehouse alone does not fix this because storage and access are different problems.
The target operating model: centralized foundations, distributed analysis
The most practical model is not fully centralized or fully decentralized. It is a controlled division of responsibility.
The central data or BI function should own the foundations that benefit from consistency: ingestion, transformation standards, core business definitions, certified datasets, access patterns, monitoring, lineage, and platform administration.
Business teams should be able to use those foundations to answer questions within their domain. A sales analyst might explore pipeline by region and product. A finance manager might investigate expense variance. A marketing lead might compare campaign performance by audience. They should not need to rebuild the definition of customer, revenue, fiscal period, or geography each time.
This creates a simple principle: centralize what must be consistent; decentralize what benefits from context and speed.
1. Start with certified datasets, not raw warehouse access
The fastest way to create self-service chaos is to point users at hundreds of warehouse tables and call it empowerment.
Raw and staging tables are optimized for engineering workflows, not necessarily for business interpretation. They can contain duplicate records, technical keys, slowly changing dimensions, source-specific statuses, intermediate calculations, and fields whose meaning is not obvious.
Instead, create a smaller set of certified, business-oriented datasets. Each should have a clear purpose, owner, grain, refresh expectation, and documented definitions.
For example, rather than exposing CRM opportunity tables, ERP invoice tables, and separate product mappings, a certified commercial dataset might provide consistent dimensions for customer, product, salesperson, region, period, bookings, invoiced revenue, and pipeline.
Certification does not mean the dataset can answer every possible question. It means the organization explicitly trusts it for a defined set of uses.
A useful certification record should answer:
- What business questions is this dataset designed to support?
- What is the grain of each row?
- Which source systems feed it?
- How often is it refreshed?
- Which metrics are approved?
- Who owns the business definition?
- Who owns the technical implementation?
- What known limitations exist?
This small amount of discipline dramatically reduces ambiguity.
2. Build a semantic layer around business language
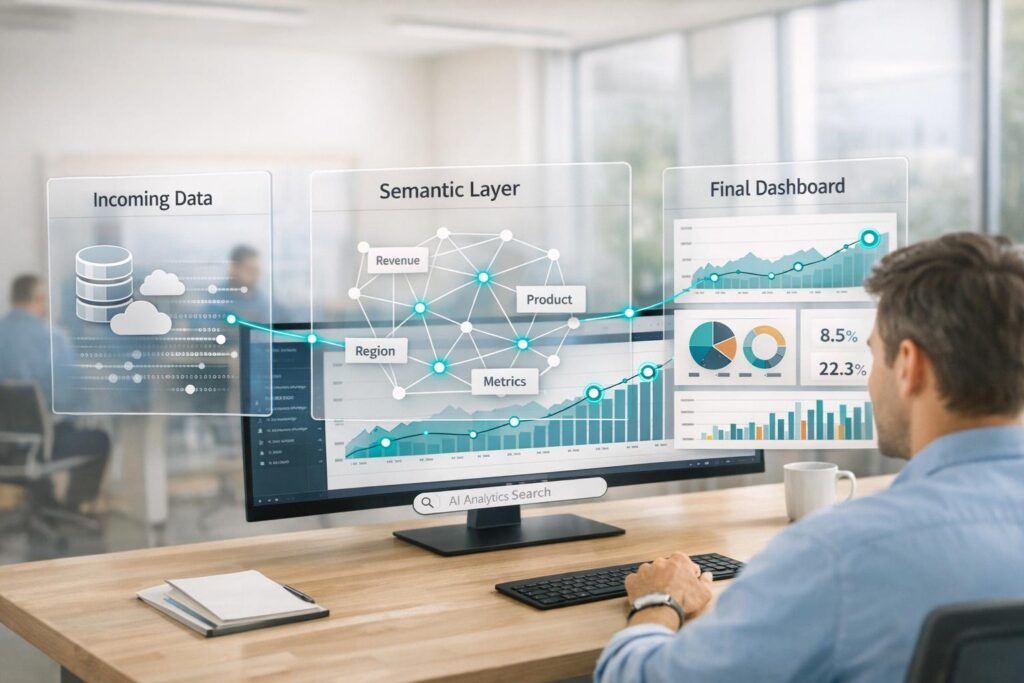
Even a clean dimensional model can still expose too much technical complexity. A semantic layer translates the data model into business concepts and reusable calculations.
The precise implementation varies by BI platform, but the principle is consistent. Measures should be defined once where practical and reused across reports rather than recreated independently by every analyst.
Consider something as apparently simple as revenue. One team may mean booked revenue, another invoiced revenue, another recognized revenue, and another cash collected. All can be legitimate. The problem occurs when they are all labeled Revenue.
A semantic model should make these distinctions explicit. The same applies to active customer, conversion rate, headcount, utilization, pipeline, retention, and margin.
The goal is not to eliminate every alternate definition. It is to make approved definitions visible, named correctly, and reusable.
3. Separate governed metrics from exploratory analysis
Self-service programs often fail because organizations try to govern everything equally.
Not every calculation needs enterprise certification. An analyst testing whether delivery delays correlate with customer churn should be able to experiment. But a churn KPI shown to the board should have a stable definition and an accountable owner.
A practical model uses levels of trust.
Certified metrics are approved for recurring executive and operational reporting. Managed departmental metrics are owned within a function and may be appropriate for team decisions. Exploratory calculations are explicitly treated as analysis rather than official reporting.
This distinction gives users room to investigate without allowing experimental logic to quietly become the company’s official number.
4. Design access controls before expanding access
Self-service increases the number of people interacting with data, so security must be designed into the operating model.
Access should be based on role and legitimate need. Sensitive fields should not become broadly visible simply because they exist in a convenient dataset. Depending on the platform and use case, controls may include workspace permissions, object permissions, row-level security, column restrictions, masked data, separate datasets, and controlled exports.
Actiknow’s published security practices describe least-privilege access, minimum necessary permissions, encrypted connections, OAuth where possible, multi-factor authentication for administrative access, and review of IAM policies and security roles. These principles are directly relevant when broadening analytical access.
A useful test is simple: if a user gains access to a self-service dataset, what is the maximum information they could see, query, export, or combine? Security reviews should answer that question before rollout, not after an incident.
5. Treat the metric dictionary as a product
A data dictionary that nobody reads is not governance.
Business definitions should be easy to find at the point where users need them. For important measures, document the name, plain-language meaning, calculation logic, exclusions, time basis, source, owner, refresh frequency, and examples of correct and incorrect interpretation.
Definitions also need change control. If Finance changes the treatment of refunds in net revenue, the organization needs to know when the definition changed, which reports are affected, and whether historical values are restated.
This matters because self-service multiplies reuse. A flawed central metric can spread quickly, but so can a well-governed one.
6. Create reusable analytical building blocks
The best self-service environments reduce the amount of work required to ask the next question.
Common dimensions such as date, customer, product, location, channel, employee, and account should behave consistently across subject areas where possible. Reusable measures should be preferred over repeated calculations. Standard filters and hierarchies should reflect how the business actually operates.
This turns analytics into composition rather than reconstruction.
A regional manager who wants revenue by product and month should be combining trusted components, not reverse-engineering source tables. This is also why good data modeling matters as much as dashboard design.
7. Give users guardrails, not just training
Training is necessary, but training alone cannot compensate for a confusing model.
A two-hour BI workshop will not make users successful if they face 400 ambiguously named fields. Good self-service design reduces the number of ways users can make reasonable-looking mistakes.
Use business-friendly names. Hide technical fields that are not intended for analysis. Group measures logically. Provide sensible default date relationships. Clearly distinguish amounts from counts and percentages. Explain which fields can be combined safely. Provide a small number of reference reports that demonstrate intended usage.
Training can then focus on analytical thinking: choosing the right metric, understanding grain, interpreting filters, distinguishing correlation from causation, and validating unusual results.
8. Build an escalation path for questions that should not be self-service
The aim is not to eliminate the BI team from reporting. Some questions genuinely require specialist work.
Complex identity resolution, new source integration, changes to accounting logic, predictive modeling, large-scale transformations, sensitive-data analysis, and cross-domain metric disputes should normally involve appropriate specialists.
The self-service model should therefore define three outcomes for a user question: answer it independently using certified assets; ask a domain expert for interpretation; or escalate it to the data team because the underlying model must change.
This prevents self-service from becoming an excuse to push technical responsibility onto business users.
9. Measure the bottleneck itself
Executives should ask whether self-service is actually reducing friction.
Useful measures include recurring report requests per month, median time to fulfill an analytical request, percentage of common questions answerable from certified datasets, reuse of certified models, number of duplicate reports, support requests by category, adoption among intended users, and the percentage of executive KPIs sourced from governed definitions.
Do not optimize for dashboard count. More dashboards can indicate more fragmentation rather than more value.
A particularly useful metric is repeat demand. If the BI team receives the same type of request every month, that request is a candidate for a reusable dataset, measure, workflow, or report.
10. Use a hub-and-spoke ownership model
At scale, one central team cannot understand every operational nuance. At the same time, completely independent departmental BI teams often recreate inconsistent metrics and pipelines.
A hub-and-spoke model can balance both needs.
The central hub owns platform standards, core data products, security patterns, shared dimensions, certified enterprise metrics, and governance processes. Domain spokes contain analysts or power users close to Finance, Sales, Marketing, Operations, or other functions. They build and interpret analysis using governed foundations and contribute requirements back to the hub.
The relationship should be collaborative rather than gatekeeping. The central team provides reliable infrastructure and standards. Domain teams provide business context and faster local analysis.
11. Do not confuse self-service with no-code
No-code and low-code features can make analytics accessible, but ease of clicking does not eliminate the need to understand data.
A user can create an incorrect result in a visual interface just as easily as in SQL. The underlying risks remain: wrong joins, double counting, inappropriate filters, mixed grains, incomplete time periods, and inconsistent definitions.
Therefore, evaluate self-service capability by the reliability of decisions it enables, not by how little code a user writes.
12. Make the warehouse observable and dependable
Self-service increases the importance of reliability. When dozens of users depend on a certified dataset, a silent pipeline failure has a wider blast radius.
Monitor freshness, row-count anomalies, failed loads, schema changes, critical transformations, and other controls appropriate to the data. Make freshness visible to users so they can distinguish a genuine business change from delayed data.
The operating question is not merely, Did the pipeline run? It is, Can users reasonably trust that the data is complete enough and current enough for the decision they are making?
A phased roadmap from warehouse to self-service
A self-service program is safer when implemented incrementally.
Phase 1: Identify demand. Review the BI backlog and recurring ad hoc requests. Identify the domains creating the most repetitive work and the decisions those requests support.
Phase 2: Stabilize definitions. Select a manageable set of high-value metrics and dimensions. Resolve ownership, calculation, grain, time basis, and reconciliation rules.
Phase 3: Build certified data products. Create business-oriented datasets and semantic models for the selected domain. Validate them against known source reports and edge cases.
Phase 4: Apply security. Define roles, sensitive fields, row-level restrictions where needed, workspace access, export expectations, and administrative controls.
Phase 5: Pilot with real users. Choose a small group of business users and give them actual questions to answer. Observe where they become confused rather than simply asking whether they like the tool.
Phase 6: Enable and document. Provide concise guidance, examples, definitions, ownership contacts, and a clear escalation process.
Phase 7: Measure and expand. Track request volume, adoption, duplicated work, data issues, and time to answer. Expand to another domain only when the first model is stable enough to support itself.
Where self-service analytics commonly goes wrong
The first failure mode is democratizing raw data instead of curated data. Users receive access but not understanding.
The second is allowing every team to define its own enterprise KPIs. Exploration becomes fragmentation.
The third is treating governance as an approval committee. If every new measure requires weeks of process, users route around governance.
The fourth is underinvesting in model design. A beautiful BI interface cannot rescue an ambiguous data model.
The fifth is ignoring adoption. A technically excellent semantic model that business teams cannot understand simply creates a newer version of the old bottleneck.
The sixth is expanding access without expanding controls. Self-service must increase analytical reach without casually increasing exposure of sensitive data.
The executive decision: what should be centralized?
A simple test helps determine where a capability belongs.
Centralize it when inconsistency creates material risk, duplication is expensive, security is important, or many teams depend on the same definition. This usually includes core pipelines, identity rules, enterprise dimensions, executive KPIs, access standards, and platform administration.
Decentralize it when domain context matters more than universal consistency and the analysis can safely use governed foundations. This often includes local slicing, exploratory analysis, departmental views, temporary investigations, and presentation choices.
The boundary will differ by organization, but it should be deliberate.
What good looks like
A mature self-service environment does not mean the BI team has nothing to do. It means the team spends less time repeatedly extracting and rearranging the same information and more time improving data products, quality, architecture, and difficult analysis.
Business users gain speed without having to become engineers. Executives see fewer debates about whose spreadsheet is correct. Analysts can trace important metrics to governed definitions. Sensitive data remains controlled. New questions can often be answered by recombining trusted building blocks rather than starting another development project.
That is the real payoff: not more reports, but a shorter path from question to trustworthy answer.
Frequently Asked Questions
What is self-service analytics?
Self-service analytics is an operating model in which authorized business users can independently explore and analyze trusted data for appropriate questions, using governed datasets, reusable definitions, and access controls rather than depending on a central BI team for every report.
Does self-service analytics eliminate the need for a BI team?
No. It changes the BI team’s role. Central specialists remain important for data engineering, shared models, security, governance, complex analysis, monitoring, and platform management. Self-service reduces repetitive report-building work rather than eliminating specialist expertise.
Should business users have direct access to the data warehouse?
Not necessarily. Direct access may be appropriate for technically capable analysts, but most business users are better served by curated datasets or semantic models that hide unnecessary complexity and expose approved business concepts.
What is a certified dataset?
A certified dataset is a data asset that an organization has explicitly approved for defined business uses. It should have known sources, grain, ownership, refresh expectations, metric definitions, and documented limitations.
What is the role of a semantic layer in self-service analytics?
A semantic layer presents data using consistent business concepts and reusable calculations. It helps prevent users from independently rebuilding important metrics and reduces the technical knowledge required to explore governed data.
How do you prevent different departments from creating conflicting KPIs?
Start by identifying which KPIs require enterprise consistency, assign business owners, document approved definitions, implement reusable calculations where practical, and distinguish certified reporting from exploratory or departmental analysis.
How should self-service analytics be secured?
Use least-privilege access and controls appropriate to the platform and data, such as role-based permissions, row-level security, restricted sensitive fields, controlled workspaces, secure authentication, and clear export policies. Test what each user role can actually see, not merely what administrators expect it to see.
How can executives tell whether self-service analytics is working?
Look for shorter turnaround on routine questions, fewer repetitive BI tickets, increased reuse of certified datasets, reduced duplicate reporting, wider adoption among intended users, and fewer disputes about core metric definitions. The objective is faster trusted decisions, not simply more dashboards.
Call to action
If your data warehouse is working but your BI team has become the queue for every business question, the next investment may not be another dashboard. It may be a better analytical operating model. Actiknow can help assess the data integration, modeling, dashboard, automation, and governance work required to create a practical self-service layer. Contact Actiknow to discuss where your current reporting bottleneck sits and what should be standardized before access is expanded.