
Executive summary: eliminate unnecessary copies, not necessary independence
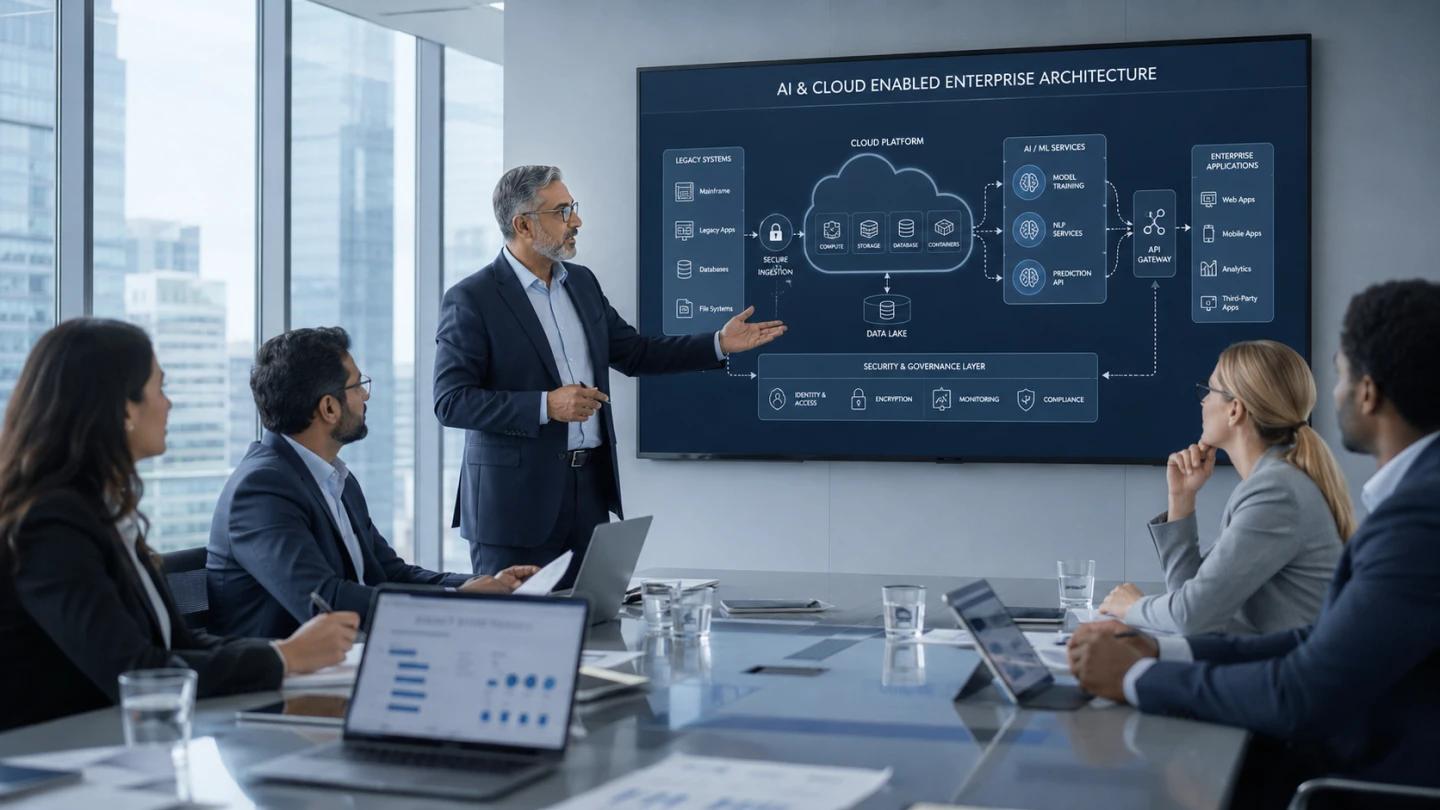
Every new analytics team seems to ask for its own version of the same warehouse tables. Finance wants governed revenue data, marketing wants customer activity, and a regional business unit needs a different reporting cadence. A conventional response is to copy the data: build another ETL pipeline, load another warehouse, and reconcile the two when someone notices that yesterday’s numbers do not match. Amazon Redshift data sharing offers a different architecture. A producer warehouse exposes selected live database objects to authorized consumer warehouses without creating a second physical copy of those shared tables.
That does not make data sharing the universal answer. A shared dataset can reduce duplication and synchronization work, but it still needs consumer compute, permissions, cost controls, dependency management, and a clear owner for the underlying data. Some workloads genuinely require a physical copy for resilience, transformation, long-term reproducibility, contractual isolation, or a different platform. The leadership decision is not whether data sharing is modern. It is whether the business needs a current, governed view of one source of truth or an independently managed dataset.
A useful starting rule: share when multiple Redshift consumers need consistent, current data and can accept producer dependencies; copy when consumers need to change, preserve, distribute, or operate the data independently. Evaluate each dataset and workload rather than applying one policy to the entire enterprise.
What Redshift data sharing actually does
Redshift organizes sharing around a producer and one or more consumers. The producer owns the data and defines a datashare containing permitted database objects. A consumer associates with that datashare, creates a local database reference, and queries shared objects using its own warehouse compute. Data remains stored with the producer. Amazon documents support across provisioned clusters and Redshift Serverless workgroups, including eligible cross-account and cross-Region arrangements. For a detailed technical explanation, see AWS’s overview of Redshift data sharing.
A producer can publish a carefully chosen schema, table, or view rather than expose an entire analytical estate. The consumer can combine shared data with its own local tables for business-specific analysis. Changes committed by the producer become visible to new consumer transactions, subject to transaction consistency. This is live analytical access, not a batch replication schedule. It also is not a substitute for source ingestion: the producer must still load, clean, model, and validate its underlying data.
Historically, many descriptions of Redshift sharing assumed read-only consumers. Current Redshift capabilities also support controlled multi-warehouse writes in eligible configurations. Write access is not automatic: it requires explicit producer grants and, for cross-account scenarios, appropriate authorization and association settings. For the typical executive reporting use case, start with read-only access and treat shared writes as a separately governed design choice.
What remains separate
Consumer compute and workload tuning remain separate from producer compute. A large reporting query is executed using consumer resources, so business units can scale and budget their own workloads. Data ownership, object lifecycle, and primary storage remain with the producer. These are different kinds of separation: sharing can isolate query workloads without isolating the underlying dataset’s availability or schema-change risk.
Five situations where live sharing is usually the stronger design
1. Several teams need the same approved metrics
Consider a revenue mart that feeds finance reporting, executive dashboards, and regional performance reviews. If each team copies and transforms the mart, metric definitions can drift. Sharing a governed, documented version keeps consumers closer to a common definition. Teams may still build local presentation layers, but they should not silently change the meaning of net revenue, active customer, or booked order. The advantage is governance as much as reduced storage.
2. Data freshness matters more than snapshot independence
If dashboards must reflect newly committed transactions quickly, an hourly or nightly ETL copy creates an additional freshness boundary. Live sharing removes that copy-specific lag. It does not make ingestion instantaneous, and it does not guarantee that an upstream source is current. Define freshness from the original business event through ingestion, transformation, and final dashboard. Otherwise a technically live share can still deliver stale business information.
3. Workloads need different compute profiles
A centrally maintained dataset may serve ad hoc analysts, scheduled BI extracts, and resource-intensive forecasting queries. Separate consumer warehouses can size compute to their own concurrency and performance requirements while reading common producer data. This is useful when an overloaded reporting workload should not dictate how the ingestion and transformation warehouse is provisioned. It is less useful when a single modest cluster already meets all service levels.
4. Different AWS accounts need controlled collaboration
Business units or affiliated organizations may have separate AWS accounts for billing and administrative boundaries. Redshift supports cross-account sharing with an explicit producer authorization and consumer association process. That handshake is a governance advantage, but it requires account-level ownership and periodic review. Do not assume a cross-account share is secure merely because the accounts are separate; inspect exactly which namespaces and users can query the objects.
5. Teams want to reduce duplicate pipelines
A duplicated dataset has ongoing costs beyond storage: ingestion jobs, scheduling, monitoring, schema migration, error handling, reconciliation, and incident response. If the destination copy adds no necessary transformation or independence, those tasks may be avoidable. Teams can then invest more in reliable upstream models, metadata, data quality checks, and consumer-facing documentation.
When a physical copy is the right answer
Data sharing is a dependency, not a magic replacement for replication. A copy may be necessary when the consumer must retain a fixed historical snapshot for an audit, maintain an independent recovery path, transform the source into a materially different data product, or serve a non-Redshift platform. A copy may also be appropriate when regulatory or contractual rules require separate storage, a particular residency arrangement, or independently controlled retention and deletion.
For machine learning and experimentation, the answer often depends on reproducibility. A live shared table can change between model-training runs. If results must be reproducible, materialize a versioned training dataset or capture a controlled snapshot even if discovery and feature exploration use shared data. Similarly, a finance close may require a frozen reporting state rather than an always-current operational view.
A consumer that must continue operating through producer unavailability or disruptive schema changes should not depend solely on live access. Independent copies add resilience only if their refresh, storage, security, and recovery procedures are themselves reliable. A stale or untested replica is not a credible disaster-recovery strategy.
Cross-platform consumption is another boundary. If the target is a different warehouse engine, operational application, external file exchange, or data lake workflow, an appropriate ETL, ELT, export, or integration path may still be required. The fact that Redshift can share objects among its own warehouses does not eliminate every data movement requirement.
A decision framework for architecture reviews
Score each proposed dataset on six dimensions. Freshness: how many minutes or hours of lag can the business tolerate? Independence: must the consumer survive producer outages and schema changes? Transformation: does the consumer need a distinct, persisted model? Governance: who owns definitions, access, retention, and audit? Economics: what are the compute, transfer, pipeline, and storage costs under actual workload? Reproducibility: must a report or model be rerun against the same historical state?
If freshness is strict, independence is modest, transformation is limited, and the consumers are eligible Redshift warehouses, sharing is a strong default candidate. If independence, reproducibility, or transformation dominates, favor a materialized copy or a hybrid. If neither design meets access-control requirements, redesign the data product before choosing the transport.
Illustrative decision matrix
Executive KPI dashboard across two Redshift workgroups: prefer live sharing, provided producer uptime and metric definitions are governed. Month-end regulatory archive: prefer a frozen, controlled copy. Data science sandbox exploring the latest customer segments: use a read-only share for discovery and versioned snapshots for experiments. Third-party application requiring a relational database outside Redshift: plan an integration or export. Cross-Region executive reporting: compare sharing with replication after measuring query frequency and transfer volume.
These are architectural examples, not Actiknow client case studies or promises of performance. A workload benchmark and a security review should decide the final design.
The real cost comparison: compute, copies, transfer, and operations
The phrase ‘zero-copy’ describes the absence of a duplicate physical copy of the shared tables. It does not mean zero cost. AWS states that consumers pay the compute required to query shared data, while producers pay for the underlying storage. Cross-Region sharing adds data-transfer charges paid by the consumer. Within one Region, the cross-Region transfer charge does not apply. See the official Redshift data-sharing considerations for the current charging model.
A sensible total-cost comparison covers four buckets. First, producer-side data ingestion, modeling, and storage. Second, consumer query compute and any concurrency scaling or serverless usage. Third, data movement, including cross-Region charges for shared queries or transfer charges for replication. Fourth, operating costs: ETL maintenance, monitoring, reconciliation, incident handling, permissions, and testing. Include the value of faster access to trusted data, but do not invent a monetary benefit without evidence.
For a simple illustrative model, imagine three departments each copying a 2 TB curated dataset every day. The headline storage duplication is visible, but it is not the entire bill. You must also estimate how often those 2 TB are actually rewritten, how incremental pipelines behave, compression, warehouse sizing, and the query demand after sharing. A live design can reduce copies while increasing interactive compute demand. Conversely, a heavily reused local aggregate can be cheaper than repeatedly scanning remote shared detail, particularly across Regions. Use measured bytes scanned, query counts, and billing data rather than this illustrative volume to make a purchasing decision.
Cross-Region cost deserves its own guardrail. AWS documents query-related transfer charges, usage limits, and monitoring for cross-Region sharing. Establish a budget, track consumption by consumer, and define whether threshold actions should alert or restrict use. Before committing, test representative queries, especially wide scans, joins, and dashboards that refresh frequently.
The producer should publish a deliberately scoped data product, not a broad dump of operational tables. Assign a business owner for data meaning, a technical owner for schema and refresh, and a security owner for access policy. Maintain an inventory of datashares, included objects, consumers, permitted actions, and approval records. Restrict personally identifiable information and confidential fields using supported object-level designs and validated security controls.
The cross-account workflow requires deliberate actions on both sides. Producer administrators grant access to consumers; consumer administrators associate the share with approved accounts or namespaces and grant appropriate database privileges to users or roles. Where possible, prefer narrowly scoped namespace association rather than granting every future namespace in an account access by default. For a step-by-step model, AWS describes the cross-account authorization workflow.
Security policies need testing from the consumer’s actual identity, not only from an administrator session. Verify that the intended roles can see approved objects and cannot query restricted ones. Check how row-level security, masking, views, and permission propagation behave for the exact supported Redshift configuration. Do not assume every policy behaves identically across shared objects and locally stored tables.
If you enable multi-warehouse writes, add a separate control plane: explicit write permissions, approved tables, transaction ownership, concurrency testing, and audit trails. Most reporting consumers should not need INSERT, UPDATE, or CREATE on producer data. A write-capable share changes the risk profile from ‘who can see the data?’ to ‘who can change the authoritative data?’
A practical read-only implementation pattern
The following is a conceptual SQL sequence based on documented Redshift datashare operations. Replace identifiers and object names with your environment’s approved values. Exact commands and permissions vary with account boundaries, namespaces, engine versions, and whether you use provisioned or serverless resources. Validate in a nonproduction environment first.
— On the producer, create and populate a narrow share
CREATE DATASHARE finance_reporting_share;
ALTER DATASHARE finance_reporting_share ADD SCHEMA reporting;
ALTER DATASHARE finance_reporting_share ADD TABLE reporting.daily_revenue;
GRANT USAGE ON DATASHARE finance_reporting_share
TO NAMESPACE ‘<approved-consumer-namespace-guid>’;
For a cross-account share, the producer account must also authorize the appropriate consumer and the consumer account must associate it. These account-level actions are separate from adding an object to the datashare. On the consumer, an authorized administrator creates a local database reference to the inbound share:
— On the consumer, after authorization and association
CREATE DATABASE finance_shared
FROM DATASHARE finance_reporting_share
OF NAMESPACE ‘<producer-namespace-guid>’;
— Query the shared data from an appropriate local connection
SELECT report_date, SUM(net_revenue) AS net_revenue
FROM finance_shared.reporting.daily_revenue
GROUP BY report_date;
For production use, consider creating the consumer database with appropriate granular-permission options, assigning role-based access, and validating object visibility before any dashboard is connected. The objective is not to minimize the number of SQL statements. It is to make ownership, access, and failure behavior explicit.
Four-week pilot: prove the architecture before scaling it
Week 1: select the data product and define acceptance criteria
Choose one mature curated dataset, two real consumer workloads, and a representative group of users. Document the producer, consumer namespaces, Regions, accounts, table sizes, update frequency, critical KPI definitions, sensitive fields, and existing copy pipelines. Agree on measurable targets for query latency, freshness, data correctness, monthly spend, and recovery behavior. Record current ETL operating effort and actual query demand as a baseline.
Week 2: configure sharing and permissions
Create a least-privilege read-only datashare, complete the required account or namespace approvals, and expose only approved objects. Implement a consumer database and test role-specific access. Review encryption, audit logs, data classification, and any applicable masking or row-level controls. Create a documented access revocation test, including who can execute it and how quickly the consumer loses access.
Week 3: benchmark performance, cost, and failure modes
Run the same representative dashboard queries against the existing copied dataset and the shared dataset. Include concurrency peaks, typical joins, large scans, and fresh data after producer commits. Measure consumer compute, cross-Region bytes where applicable, query latency distribution, and operational alerts. Deliberately test an upstream refresh failure, a revoked share, and a schema change in a staging environment. Record whether the consumer experience fails safely and visibly.
Week 4: decide, document, and operationalize
Produce a short architecture decision record: which datasets will be shared, which remain copied, and why. Assign named owners, a change-notification procedure, a service-level agreement, a cost budget, and an incident runbook. If the pilot passes, migrate one reporting workload at a time, reconcile outputs, and retire redundant pipelines only after an agreed observation period. If it fails, retain the copy and document the specific constraint rather than forcing the new architecture.
Operational controls that prevent a successful pilot from becoming a fragile platform
Treat shared datasets as published products. Give each one a data contract specifying schema, field meanings, refresh cadence, quality tests, deprecation policy, and an escalation contact. Publish planned breaking changes before implementation. Where feasible, use versioned views or a compatibility period so downstream consumers can migrate deliberately. Changes to an authoritative model can otherwise break many teams at once.
Monitor both producer and consumer sides. Producer checks should cover ingestion freshness, model tests, table availability, and schema changes. Consumer checks should cover query errors, latency, workload utilization, access denials, and actual dashboard freshness. Add cost attribution by account, workgroup, team, or business product. A green producer pipeline does not prove that consumers can query the right data.
Design recovery and exit paths. Document who can revoke a share, how consumers will be notified, whether a critical dashboard needs a fallback snapshot, and how to recreate permissions after an infrastructure change. Define what happens when a producer is retired or an organization separates accounts. A shared data product should have an explicit lifecycle rather than become an undocumented permanent dependency.
For BI teams, the integration between warehouse data and executive reporting is where governance becomes visible. Actiknow’s business intelligence consulting and integration services describe work across data sources, models, and reporting tools; the same discipline of clear definitions and validation is essential when choosing a shared warehouse architecture.
Common mistakes to avoid
Mistake one: choosing data sharing only to reduce storage while ignoring consumer query cost. Mistake two: sharing raw operational tables instead of stable, documented business models. Mistake three: granting access to an entire account when only a few namespaces need it. Mistake four: assuming ‘live’ guarantees that source ingestion is fresh. Mistake five: enabling shared writes without an explicit business reason and transaction controls.
Mistake six: retiring copies before testing producer failure, permission revocation, and schema changes. Mistake seven: using shared detail tables for high-frequency cross-Region dashboards without measuring transfer fees. Mistake eight: letting teams publish different KPI definitions over the same shared dataset. A well-designed architecture must address all eight, not simply demonstrate that a SELECT query works.
Executive acceptance checklist
Before declaring a shared data product production-ready, ask for evidence of the following: a named producer owner and consumer owner; an approved object inventory; a data classification and access review; successful least-privilege role tests; freshness and reconciliation results; peak-concurrency benchmarks; a measured cost comparison; a schema-change communication process; incident and revocation runbooks; and an explicit decision about whether any consumer needs a frozen or independently recoverable copy.
A business-facing data visualization layer should use these same approved definitions and freshness expectations. Where dashboards are the primary consumers, Actiknow’s data visualization services page outlines the related work of integrating data sources, building reporting experiences, and testing performance.
Frequently asked questions
1. Does Redshift data sharing create another physical copy of the data?
No. Standard Redshift data sharing lets eligible consumer warehouses query selected producer objects without materializing a second copy of those shared tables. A consumer may still choose to create local tables or snapshots for a separate purpose.
New consumer transactions can see producer changes after those transactions commit. The actual business freshness still depends on upstream ingestion and transformations. Define and monitor an end-to-end freshness service level.
3. Does a consumer use the producer’s compute?
Consumer queries use consumer compute, allowing workload-level scaling and cost attribution. The producer remains responsible for the stored authoritative data and its preparation.
Yes, for supported Redshift configurations. Cross-account access requires producer authorization and consumer association, followed by appropriate database and object permissions.
Yes, where the feature is supported. Cross-Region queries incur transfer charges for the consumer, so benchmark scan patterns and apply usage controls before broad rollout.
6. Is data sharing always cheaper than ETL replication?
No. It can eliminate duplicate storage and copy pipelines, but compute, cross-Region transfer, and operational requirements still matter. Compare total cost using actual workload measurements.
Redshift supports controlled multi-warehouse writes in eligible configurations, but write access requires explicit permissions and additional cross-account controls where relevant. Read-only sharing is generally the safer starting point for BI.
The consumer’s ability to query shared data depends on the producer-side data service and relevant platform availability. If independent operation is a hard requirement, plan a separately managed copy or another tested continuity approach.
Curated, documented marts are usually a better external contract for business reporting. Raw tables can expose unstable schemas, sensitive fields, and inconsistent semantics. Choose object granularity deliberately.
10. How should we handle schema changes?
Publish a contract, assign a producer owner, notify consumers before breaking changes, and test dependent queries. Versioned views or compatibility windows can reduce disruption.
11. Is data sharing a replacement for a data warehouse migration?
No. It can simplify distribution among Redshift warehouses but does not automatically migrate applications, transform data, or support every external engine. Migrations still need mapping, validation, and cutover planning.
12. What is the best first workload for a pilot?
Choose a stable curated table used by two reporting teams, with measurable freshness needs and known query patterns. Avoid the most sensitive or business-critical dataset for the first technical test.
The decision that matters
Redshift data sharing is valuable when it replaces unnecessary duplication with controlled access to a common data product. The win is not just fewer ETL jobs. It is the combination of clearer ownership, consistent definitions, workload-specific compute, and a more direct route from validated data to decisions. But when consumers need isolation, reproducibility, or an independent lifecycle, a physical copy remains a legitimate architectural choice.
If your team is weighing live Redshift sharing against duplicated warehouse pipelines, Actiknow can help scope a focused BI architecture and reporting review. Start with a conversation through the Actiknow contact page, using one real dataset and one real reporting workload to make the tradeoffs measurable.
Technical references
This article is informed by AWS documentation on Redshift data sharing, cross-account authorization, general considerations, and cross-Region cost controls. Feature support and pricing vary by configuration and may change; validate the current documentation and your own account settings before deployment.