Natural-language analytics changes the interface to data, but it does not change the standard for executive reporting.
A CFO asking a question in plain English still expects the same revenue definition used in the board pack. A sales leader still expects the correct fiscal period. A regional manager must still see only authorized records.
Platforms are increasingly adding formal evaluation features. Snowflake can evaluate semantic views against verified queries and report accuracy, regressions and latency. Tableau Next’s Q&A Calibration similarly focuses on curated questions and systematic validation of agent answers.
That direction is important: enterprise conversational analytics needs a test discipline.
Actiknow’s Business Intelligence services include modeling, data integration, quality checks and ongoing maintenance. Those practices provide the foundation for validating an AI interface to business data.
Why Testing Is Different
A dashboard exposes predefined calculations. Natural-language analytics lets users generate new query shapes at runtime. The system can select the wrong metric, apply the wrong date, misunderstand a business term, choose an incorrect relationship or answer a question that should have been clarified. A polished sentence is not evidence of correctness. Testing therefore needs a benchmark of business questions and expected analytical behavior, not only software uptime.
Start With Executive Questions
Collect real questions from executives, analysts and existing dashboards. Include simple KPIs, comparisons, drilldowns, rankings, filters and ambiguous language. Do not create a benchmark made only of easy questions the system already answers. The purpose is to represent the decisions people will actually make.
Create Ground Truth
For every benchmark question, record the approved metric, dimensions, filters, time range and expected result. Where possible, retain validated SQL. Snowflake verified queries pair natural-language questions with expected SQL, and its evaluation framework can compare generated results against that ground truth. Ground truth must be owned by business data experts, not inferred by the model.
Use Absolute Dates in Regression Tests
A test that asks for last quarter changes meaning over time. Snowflake specifically warns that time-relative verified queries can make evaluation results drift. Use fixed periods in regression suites, such as Q2 2026, so a change in result reflects a system change rather than the calendar.
Test Meaning, Not Just SQL Text
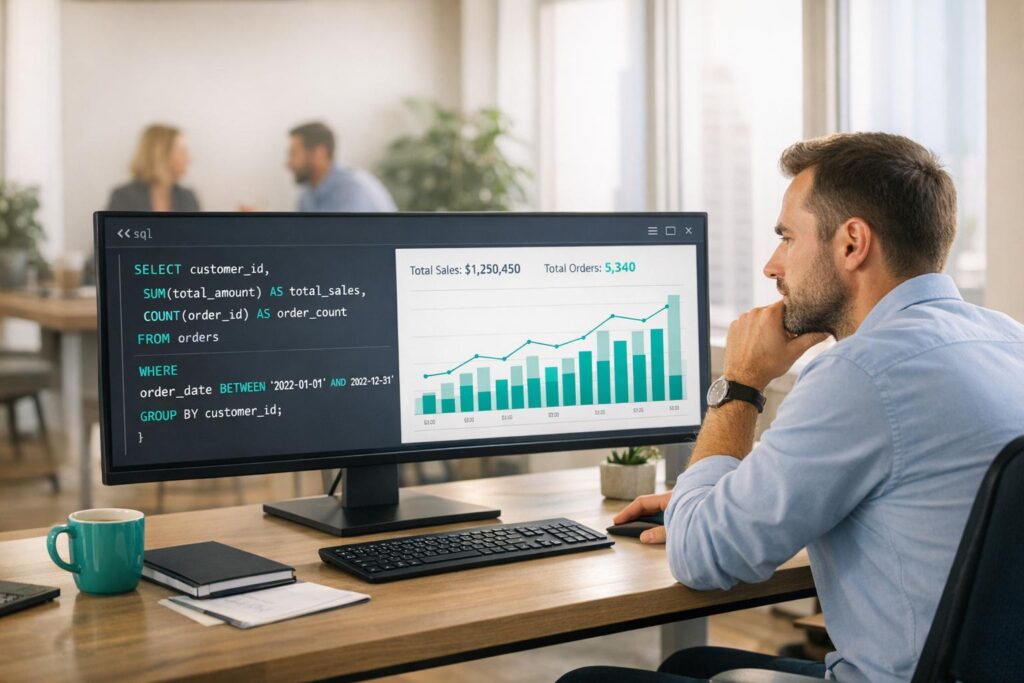
Two different SQL statements can produce the same correct answer. Conversely, similar-looking SQL can produce different results. Evaluate metric selection, filters, grain and output. Where the platform provides result-based correctness evaluation, use it. Human review is still important for high-value business semantics.
Test Ambiguity
Questions such as How are sales doing? are incomplete. Define expected behavior. The system may ask which sales metric and period the user means. A trustworthy analytical agent should not be rewarded for always answering. Sometimes clarification is the correct result.
Test Wrong Questions
Include questions the model should refuse or route elsewhere. Ask for data outside the semantic domain, restricted information, unsupported forecasts and nonexistent fields. Good evaluation includes safe failure.
Test Security
Run the same question as users with different permissions. Confirm row restrictions, masking and tenant boundaries. An answer can be numerically correct and still be a security failure if the user should never have received it.
Test Relationships
Create questions that cross tables. Validate one-to-many joins, optional relationships and fan-out risk. Natural-language systems can generate valid SQL over an invalid analytical relationship. Reconcile totals against trusted reports.
Test Time Logic
Cover fiscal year, calendar year, month-to-date, year-over-year, cohort dates and timezone boundaries. Record which date field belongs to each metric. Many executive disputes that look like AI errors are actually unresolved time semantics.
Test Filters and Synonyms
Use the language people actually use. Test abbreviations, product nicknames, region names and business synonyms. But do not teach the system that two terms are synonyms when the business distinguishes them. Accuracy requires semantic precision.
Test Multi-Turn Context
If the product supports follow-up questions, test context explicitly. Ask a base question, apply a filter in the next turn, change the period, then change the metric. Confirm old context is retained or discarded as expected. Single-turn accuracy does not prove conversational accuracy.
Test Latency
Executives will abandon a system that is correct but painfully slow. Track response latency alongside correctness. Snowflake evaluations record latency in addition to accuracy and regressions. Define acceptable ranges for common question types.
Measure Regressions
A release is risky when questions that were previously correct become wrong. Track that separately from overall accuracy. A system can improve from 80 to 85 percent overall while breaking a critical CFO question. Critical benchmark questions should have release-blocking status.
Use Curated Question Sets
Tableau Next’s Q&A Calibration is designed around curated questions, expert classification and batch regression testing. The broader principle is platform-independent: data experts should maintain a representative question set and rerun it as semantic models evolve.
Separate Semantic Errors From Data Errors
If the warehouse contains duplicate transactions, the natural-language layer may faithfully return the wrong total. Classify failures as source data, transformation, semantic definition, query generation, retrieval, permission or presentation. This prevents teams from endlessly tuning prompts for a data-quality defect.
Create Severity Levels
Not every failure has equal impact. A wrong board-level revenue number is critical. A poor chart choice may be minor. Assign severity based on decision impact, frequency and detectability. Release gates should focus on critical and high-severity failures.
Establish Accuracy Thresholds
Avoid one universal accuracy percentage. Define minimum performance by domain and question class. Finance may require near-perfect benchmark performance for governed KPIs. Exploratory marketing questions may tolerate more clarification. Publish the thresholds before testing.
Human Review
Use business SMEs to review representative outputs. They should validate not only the number but the interpretation. Ask whether the answer would cause the user to make the intended decision. A technically correct answer with misleading framing can still fail.
Version the Evaluation Set
Store benchmark questions, expected SQL or results, owners and revisions in version control or another governed repository. When a business definition changes, update the expected answer deliberately and record why. Otherwise teams cannot distinguish an intended policy change from a regression.
Release Process
Treat semantic changes like software changes. Develop, test, review, deploy and monitor. Run the benchmark before production. Compare results with the prior release. Require approval for changes affecting critical metrics.
Production Feedback
Add a way for users to flag questionable answers. Preserve request identifiers, filters and generated queries where the platform supports them. Review recurring failures and convert valuable cases into benchmark questions. Production usage should continuously improve the test suite.
Do Not Train on Every Complaint
A user may be wrong. Investigate before converting feedback into a verified query or semantic rule. Snowflake’s suggestion workflow requires human review before proposed model elements are accepted. That is the correct governance pattern.
Compare Against Existing BI
During rollout, compare high-value answers with trusted dashboards and reports. Differences are not automatically AI failures; sometimes the dashboard contains legacy logic. Reconciliation forces the organization to identify which definition is authoritative.
Pilot With a Small Group
Begin with data-literate users who will challenge results. Give them supported domains and known limitations. Capture failures. Fix the semantic layer. Then expand. Executive launch should follow evidence, not precede it.
Monitor After Launch
Track question volume, accuracy feedback, clarification rate, unsupported questions, latency and regressions. Model and platform updates can change behavior even when your application code is unchanged. Natural-language analytics is an operated product.
Define Ownership
Business owners define metric meaning. Data engineering owns reliable source data. Analytics engineering owns semantic models. Security owns access policy. Product teams own the user experience. One AI engineer cannot be accountable for enterprise truth.
A Practical Benchmark
Start with 50 to 100 questions for one domain. Include roughly equal coverage of core KPIs, filters, comparisons, relationships, time logic and edge cases. Mark 10 to 20 questions as critical. Add real production failures over time. The exact number matters less than representative coverage and disciplined maintenance.
Go-Live Checklist
Before launch, confirm
- critical questions pass,
- no known security failure exists,
- metric owners approved definitions,
- unsupported questions fail safely,
- latency is acceptable,
- request tracing works,
- feedback has an owner
- rollback is possible.
If these controls are missing, the system is still a pilot.
Frequently Asked Questions
How accurate should natural-language analytics be?
There is no universal percentage. Set thresholds by decision risk and question class.
Should we test generated SQL or final results?
Test both where useful, but business correctness of the result and interpretation is the primary outcome.
How many benchmark questions do we need?
Start with a representative set for one domain and expand from real usage.
What are verified queries?
They are curated natural-language questions paired with validated SQL that can serve as guidance and evaluation ground truth.
Can executives use the system before every possible question is tested?
Yes, if supported domains and limitations are clear and critical questions have strong coverage.
Should a clarification count as failure?
No. For an ambiguous question, clarification may be the correct expected behavior.
Conclusion
Executives will trust natural-language analytics only when the organization can demonstrate how answers are validated. Build a benchmark from real business questions. Define ground truth. Test permissions, time logic, relationships and ambiguity. Track regressions. Add production failures back into the suite. The goal is not to prove that AI never makes mistakes. It is to create an engineering and governance process that detects important mistakes before they influence decisions.
Actiknow can help design the data model, semantic layer, BI reconciliation and validation process behind enterprise conversational analytics. Explore Actiknow’s Business Intelligence services or discuss your analytics requirements with Actiknow.
Operational Detail
For every failed benchmark, retain the user question, expected interpretation, actual interpretation, generated query where available, result, source data version and semantic-model version. Assign an owner and classify root cause before changing the model. After the fix, rerun the failed case and the wider regression set. This prevents a local correction from creating a new error elsewhere and turns conversational analytics into a controlled production system rather than an accumulation of prompt patches.