
Executive summary
Finance, marketing and operations often need the same trusted business data but have very different expectations of their analytics platforms. Finance needs predictable reporting during close. Marketing runs exploratory queries and campaign analysis. Operations may require dashboards that refresh frequently. When all three share one compute environment, a heavy workload can degrade an otherwise healthy report. Copying the data into three warehouses appears to solve contention but creates duplicate pipelines, reconciliation, storage and security obligations.
Amazon Redshift data sharing offers a different model: keep governed data with a central producer while independent consumer clusters or Serverless workgroups execute queries using their own compute. A February 4, 2026 AWS update extended Redshift automatic optimizations to consider query patterns across those consumer clusters. This combination makes multi-cluster analytics worth examining, but it does not mean every department needs a separate cluster or that data sharing removes the need for modeling, testing and governance.
The best starting question is practical: which workloads are failing a measurable service-level objective because they compete for compute, and what is the least expensive way to separate them? The answer may be a new consumer, better workload scheduling, query optimization or no architectural change at all.
Why departmental data copies become expensive
A conventional enterprise warehouse often starts with one shared environment. As usage grows, dashboards, transformation jobs, exports and analyst exploration arrive simultaneously. Some queries are short and predictable; others scan large histories or join many tables. A department can see slow dashboards even when its own SQL has not changed because another workload is consuming resources.
Teams may respond by exporting the same customer, sales or inventory tables into departmental stores. Every copy adds another refresh schedule, data-quality checkpoint and place where business definitions can diverge. Finance’s revenue may reflect returns processed overnight while marketing’s extract does not. Operations may use a different customer status rule. These discrepancies can consume more engineering and executive time than the original query contention.
Physical replication is still appropriate for some needs, including independent retention, regulatory segregation, non-Redshift destinations, offline access and disaster recovery. The mistake is using replication as the default answer to a compute problem when consumers simply need the same current Redshift data.
How the producer-consumer architecture works
In the common pattern, a producer Redshift environment handles ingestion, transformation and publication of curated analytical objects. It creates datashares that expose selected objects. Consumer clusters or Serverless workgroups connect to the shares and run their own analytical queries. The consumers’ query compute is separate from the producer’s query compute, reducing direct contention between those workloads.
The Amazon Redshift data sharing documentation confirms that standard sharing can span supported provisioned clusters, Serverless workgroups, AWS accounts and Regions. It describes live access to producer data without manually copying it and transactionally consistent visibility of committed changes. This does not make an upstream source instantly fresh: if the producer is six hours behind its ingestion SLA, consumers see data that is six hours behind.
A useful design might have one central curated sales model, a finance consumer for close and forecasting, a marketing consumer for attribution and ad hoc exploration, and an operations consumer for inventory monitoring. All use approved facts and dimensions while retaining control over their compute capacity, workload configuration and dashboards.
Data ownership and compute ownership are different
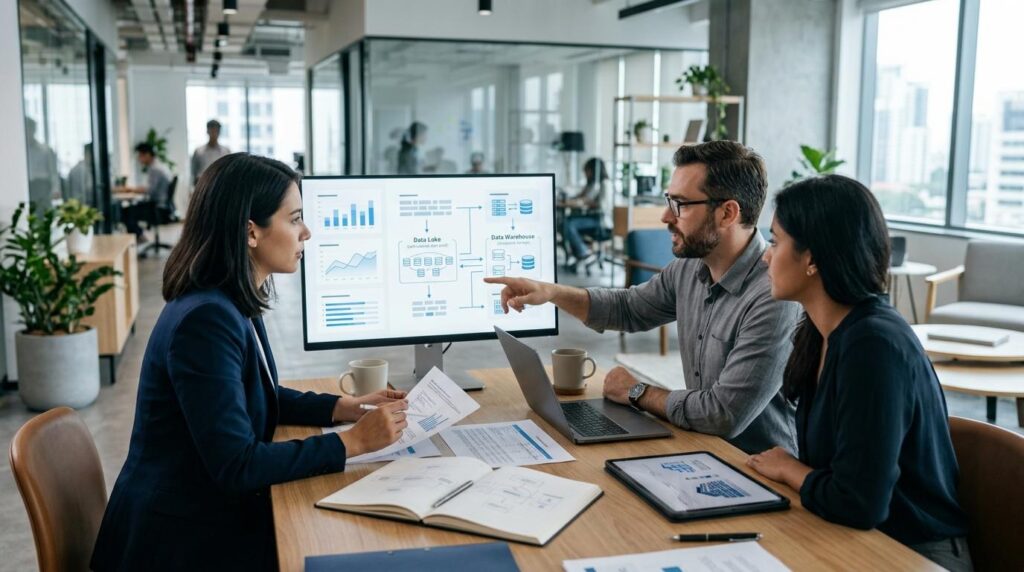
The producer owns correctness, schema contracts, refresh SLAs and the approved definition of each business measure. Each consumer owns its own query performance, local transformations, report logic and compute budget. That separation must be written down. Otherwise a slow dashboard becomes a dispute between the producer and the consumer, and an incorrect KPI becomes everyone’s problem and nobody’s responsibility.
Consumers may create local derived tables or aggregates for legitimate needs. Those local objects are not automatically governed enterprise data products. If a derived metric is reused across teams, consider promoting it to a centrally owned contract rather than allowing each department to implement a subtly different version.
What Redshift changed on February 4, 2026
The AWS February 4, 2026 announcement introduced multi-cluster support for Redshift autonomics. Automatic Table Optimization, Automatic Table Sorting, Auto Vacuum and Auto Analyze can account for query patterns from consumer clusters when maintaining and optimizing shared producer data. That is significant because the producer’s own workload may not represent the access patterns of finance, marketing or operations consumers.
The announcement also introduced a denylist capability for excluding selected endpoints or AWS accounts from influencing optimization decisions. For example, an external partner’s unusual exploratory pattern should not necessarily influence table layout decisions that affect internal business-critical reporting. AWS describes the enhancement as available at no additional feature charge in supported Redshift Regions; consumer compute, producer storage and any cross-Region transfer remain separate cost considerations.
Automatic optimization is not an automatic business policy. A data team must still decide which workloads matter, validate whether performance improves, investigate unusual consumers and monitor changes over time. An optimization that benefits one class of query may not produce equal gains for every consumer. Benchmark the actual business workload.
When separate compute makes business sense
Protect a reporting SLA
A finance dashboard needed at 8 a.m. may have a different service expectation from an analyst notebook that can run for several minutes. If query telemetry shows the dashboard’s high-percentile latency rising when exploratory work peaks, compute isolation has a clear business objective. The goal is not maximum benchmark throughput; it is reliable reporting when a decision must be made.
Allow independent scaling
A seasonal marketing workload may need substantial capacity during campaign analysis but much less afterward. A customer-facing reporting product may need stable response time during business hours. Separate consumers can be sized and operated for these patterns. Choose provisioned or Serverless based on measured demand, supported features, operating preferences and the total bill.
Clarify cost ownership
A consumer resource can be associated with a department, product or cost center. This improves showback and chargeback compared with one opaque shared compute bill. It does not make attribution perfect: the producer’s curated data, storage and central engineering remain shared services. Define how those shared costs are handled instead of assigning them repeatedly to every consumer.
Support account or organizational boundaries
Separate AWS accounts may be appropriate for subsidiaries, business units or controlled external collaboration. Cross-account data sharing supports authorization and association workflows, but the architecture needs deliberate IAM, encryption, audit and access-revocation design. A separate account is a security boundary to manage, not a replacement for object-level permissions.
When one consumer is enough
Do not equate department count with cluster count. Several low-volume teams with compatible latency requirements may share a single consumer efficiently. Conversely, one department might have both a latency-sensitive dashboard workload and an unconstrained data-science workload that deserve separate compute. Group by query behavior, concurrency, SLA and operational ownership rather than by organization chart.
Before provisioning another cluster, investigate scheduling, query design, caching, existing workload management and the impact of resizing. A well-managed single environment can be simpler and cheaper. Isolation should solve a documented problem or create a needed control boundary.
A datashare exposes database objects, not business meaning. For every shared fact or dimension, specify grain, primary business keys, time-zone treatment, currency rules, refresh cadence, quality checks, owner and approved use cases. Stable views can provide a contract that protects consumers from internal table changes, where supported and appropriate.
Consider net revenue. One team might subtract discounts at order time while another subtracts refunds when settled. If both call the result ‘revenue,’ data sharing will not reconcile them. Establish a governed metric definition before distributing access. The point of central data ownership is not merely one storage location; it is one accountable definition for shared business measures.
Actiknow’s business intelligence and data integration services describe requirements analysis, architecture, data integration, modeling, dashboard implementation and ongoing maintenance. Those same stages provide a sensible sequence for a multi-cluster evaluation: define the decision, establish the data contract, test the architecture and validate the reporting experience.
Record the producer owner; business data owner; approved objects; consuming namespaces and accounts; data classification; permitted purpose; expected freshness; schema version; breaking-change notice period; cost owner; incident contact; and revocation procedure. This can begin as a concise register rather than an elaborate governance platform. What matters is that teams can find the current contract and act on it.
Avoid sharing entire staging schemas for convenience. Publish approved analytical objects with only the necessary columns and granularity. If a department needs aggregated financial performance rather than transaction-level details, expose a suitable aggregate instead of handing out broader access and hoping the dashboard filters are sufficient.
Security and access management
Use least privilege on both sides of the share. Validate who may create a datashare, authorize a consumer, associate it with a namespace and query each shared object. Test the permissions using actual consumer roles, including negative tests that prove sensitive fields and unapproved tables are inaccessible. Audit access periodically and remove consumers that no longer need the data.
Cross-account scenarios have additional authorization and encryption considerations. Redshift standard datashare considerations also explain that restored producer or consumer clusters can have changed namespace identifiers and require permissions or consumer databases to be recreated. A disaster-recovery runbook should explicitly test these dependencies instead of assuming a snapshot restores all external relationships.
Do not accidentally grant write access
Although Redshift supports specified write-sharing scenarios, most executive BI consumers should have read access only. If a business process legitimately needs to write through a share, design it as a separate controlled workflow with explicit permissions, audit, transaction tests and an owner. Do not broaden a reporting role merely because the platform supports additional operations.
The real cost equation
Data sharing may eliminate unnecessary copy pipelines, duplicate loads and storage for equivalent datasets. It can also increase compute spend if teams provision separate consumers that sit underutilized. Compare the full cost of both designs rather than treating reduced data movement as a complete financial case.
Model producer compute and storage, consumer compute by workload, cross-Region transfer where applicable, operational monitoring, engineering support and the cost of existing pipelines that can actually be retired. Redshift’s general data-sharing considerations state that consumer query performance depends on consumer capacity, that consumers pay their compute and applicable cross-Region transfer, and that producers bear underlying storage costs.
For a credible business case, distinguish savings already realized from hypothetical savings. A duplicate ETL job does not disappear financially until it is retired. A consumer cluster does not create a saving merely because its bill can be assigned to a department. Compare like-for-like workloads across representative business periods and include the cost of unused capacity.
An illustrative, not historical, decision
Suppose finance suffers delays during month-end close because marketing runs large exploratory queries. Operations has a light dashboard used only a few times daily. A reasonable pilot isolates finance from the exploratory workload but leaves operations on shared capacity. Success means finance’s p95 reporting latency improves during comparable close windows, results reconcile, access remains correct and the incremental compute cost is justified. There is no reason to create three consumers simply because there are three departments.
What multi-cluster sharing does not solve
Stale data remains stale
Live access to producer data is not a substitute for source-to-dashboard freshness monitoring. Track source commit, ingestion completion, transformation completion, shared-object availability and dashboard cache refresh. Define which stage owns a delay and what escalation is required when a business SLA is missed.
Poor SQL remains poor SQL
An undersized consumer or expensive query can still be slow. Review joins, filtering, cardinality, aggregation grain, dashboard query repetition and concurrency. Automatic table optimization is useful, but it cannot repair an ambiguous business model or make every analytical query efficient.
Changes still break downstream consumers
A renamed column, altered business definition or removed object can affect many teams at once. Use impact analysis, versioned contracts, consumer testing and planned deprecation. Sharing reduces duplicate pipelines; it increases the importance of disciplined change communication.
Compute isolation is not complete fault isolation
Consumers still depend on producer-managed data, permissions and the underlying sharing relationship. Test behavior during upstream failures, producer maintenance, revoked access and restore operations. Separate compute protects against some contention, not every operational dependency.
A practical 30-day evaluation
Week 1: Measure the current estate
Inventory the top dashboards, query workloads, refresh jobs and duplicate datasets. Capture at least one representative business cycle of query duration, p50 and p95 dashboard latency, queue time, concurrency, failures, data freshness and cost. Identify a specific contention problem with an accountable business owner. Do not begin by drawing a new cluster topology.
Week 2: Define contracts and target boundaries
Select a small set of curated objects for sharing. Agree on metric definitions, schema expectations, access controls, freshness and ownership. Choose a consumer topology based on measured query behavior. Validate Region, account, encryption, supported objects and recovery implications. Establish cost tags and a budget before provisioning.
Week 3: Build and test
Create the share and consumer access through normal infrastructure and change controls. Run representative workloads simultaneously, including a deliberately heavy exploratory query. Reconcile row counts and key financial totals. Test restricted access as consumer roles. Observe latency, queueing, query failures, compute utilization and freshness. Document any unexpected behavior.
Week 4: Compare and decide
Evaluate p95 latency, success rate, freshness, engineering effort and actual cloud cost against the baseline. Review the effect of automatic optimization and whether any consumer should be excluded from influencing it. Test revocation and recovery steps. Expand only if the pilot demonstrates an advantage over simpler alternatives.
The scorecard executives should see
A concise scorecard should show p95 dashboard latency for business-critical reports, query success rate, freshness SLA compliance, monthly compute and transfer cost by workload, duplicate pipelines retired, and unresolved security exceptions. Add the number of shared datasets with named owners and documented contracts. This combines performance, economics and trust rather than celebrating infrastructure metrics in isolation.
The reporting experience matters as much as the warehouse benchmark. Executive dashboard implementation should validate the actual BI tool’s concurrency, query pattern, caching, refresh behavior and metric consistency. A query that looks fast in a SQL console can still result in a slow dashboard when many charts request data at once.
Frequently asked questions
Does Redshift data sharing create another copy of the tables?
Standard sharing lets consumers query live producer data without a separate physical copy for each consumer. Consumers can still create local derived objects, so audit materializations before claiming all duplication has disappeared.
Does every business unit need its own Redshift cluster?
No. Separate compute when service levels, query behavior, security or cost accountability justify it. Multiple low-volume departments can share one consumer, while a single high-volume department may need more than one workload class.
Yes, supported combinations of provisioned clusters and Serverless workgroups can participate in standard data sharing. Confirm the current configuration, Region, permissions and object limitations.
Is the data immediately fresh for consumers?
Consumers can access committed producer updates without waiting for a separate copy pipeline, but end-to-end freshness depends on source ingestion, transformation and dashboard caching.
What did the February 2026 autonomics update change?
It allowed automatic table optimization and maintenance to consider query patterns across consumer clusters, with an exclusion mechanism for selected endpoints or AWS accounts. It did not replace workload governance.
Will a new consumer automatically make dashboards faster?
No. Independent compute can reduce contention, but consumer sizing, SQL design, data model and concurrency still determine performance. Benchmark the actual dashboards.
Is cross-Region data sharing free?
No. AWS documents cross-Region transfer charges. Include them alongside compute, storage and operating costs when comparing architectures.
Redshift supports certain write-sharing use cases, but a read-only design is the safer default for BI. Explicitly authorize and test any required write workflow.
What happens after a cluster restore?
Restores may change namespace identifiers and invalidate sharing relationships, requiring permissions and consumer databases to be recreated. Include datashares in disaster-recovery testing.
The producer’s data owner should own shared data quality, definitions and freshness. Consumers own their local calculations and reporting behavior. Both need an escalation agreement.
The executive decision
Redshift multi-cluster analytics is compelling when organizations need common, governed data and different execution guarantees. Sharing provides a path away from unnecessary copy pipelines; separate compute can protect important BI workloads; multi-cluster autonomics makes optimization more aware of the wider estate. The value depends on disciplined contracts, least-privilege access, measured service levels and honest cost accounting.
Start with one real contention problem, one governed data product and one measurable pilot. Expand only when performance, governance and economics improve together. More clusters are not the goal. More dependable decisions from trusted data are.
Discuss your architecture with Actiknow
If your analytics teams are maintaining duplicate Redshift extracts or competing for reporting capacity, contact Actiknow about an analytics architecture review. A focused assessment can clarify data integration, modeling, workload boundaries and BI validation before you commit to additional infrastructure.
Technical sources
Platform-specific details are based on AWS’s Redshift documentation and its February 4, 2026 release announcement. Confirm current eligibility, pricing, regional support and limitations in your own AWS environment before deployment.