
Executive summary
Most organizations already have structured business data, but relatively few have the people, processes and infrastructure to maintain a full machine-learning platform. Customer records, transactions, support histories and operational data sit in warehouses while prediction projects struggle to move beyond a proof of concept. BigQuery TabFM offers a simpler route to an initial experiment: use SQL to apply a pretrained tabular foundation model to labeled historical records and predict outcomes for new records.
Google announced TabFM support in BigQuery on August 31, 2026. As of November 7, 2026, the capability remains in Preview. It supports classification and regression through AI.PREDICT, with AI.EVALUATE available for evaluation. The official BigQuery release notes describe the original launch. The opportunity is faster experimentation, not an exemption from data quality, validation, privacy or operational controls.
The executive question is not whether the team can run a prediction query. It is whether that query improves a specific business decision, compared with a cheaper and simpler baseline, without introducing unacceptable cost or risk. This guide explains what the technology does, where it is useful, how to test it, and what must be in place before production adoption.
What BigQuery TabFM actually is
TabFM is a pretrained foundation model for tabular data, meaning rows with structured columns such as customer tenure, product category, number of support tickets or order value. It can estimate a numerical target (regression) or assign a category (classification). Google describes its built-in implementation and the underlying research in the TabFM model documentation.
Unlike a conventional supervised workflow, a team does not have to train a new set of model parameters for every dataset, tune hyperparameters or register a task-specific model artifact before running inference. Instead, it supplies labeled examples as context to a pretrained model and asks for predictions on other rows. This is the sense in which the capability is called zero-shot.
Zero-shot does not mean prediction without business examples. AI.PREDICT still needs labeled historical rows, with the target outcome recorded, and feature columns that also exist in the rows to be scored. If renewal outcomes are missing, sales stages are unreliable or the available attributes were entered after the decision date, TabFM cannot make that information problem disappear.
Why this matters to teams without an ML platform
First, the path from business question to evaluation can become shorter. SQL-oriented analysts can prepare a sample, run a prediction and compare it with observed outcomes without first provisioning a dedicated training service. Second, the experiment can stay close to governed warehouse data rather than requiring a new data export workflow. Third, an organization can learn whether a use case merits deeper investment before committing to an extensive MLOps architecture.
None of these advantages proves that TabFM will beat a logistic regression, a boosted tree, an existing business rule or human judgment. A trained model may offer better tuning, interpretability, deployment controls or cost efficiency. The right comparison includes prediction quality, operational consequences, reproducibility, total cost and how easily the business can act on the result.
Actiknow’s business intelligence services include data integration from databases and APIs, analysis and modeling, and BI architecture. Those foundations are relevant because predictive analytics inherits the definitions, timeliness and trustworthiness of the underlying reporting environment. A predictive score is not a substitute for consistent definitions of an account, order, renewal or recognized revenue.
Four business use cases worth testing
1. Renewal and churn prioritization
A subscription business might classify accounts into renewal-risk categories using tenure, product usage, support interactions and billing changes available before renewal. The output could help customer-success managers decide which accounts deserve review. It should not automatically determine pricing, service access or eligibility. A pilot should compare the score with existing prioritization and measure whether the intervention changes an outcome.
Beware of leakage. If the historical data includes a cancellation reason entered after the customer left, a model may appear remarkably accurate while offering no advance warning. Build the dataset as it would have existed at the actual decision date. Test whether the model still performs when post-outcome fields are removed.
2. Order value or demand estimation
A distributor might use regression to estimate order value from known product, customer and channel attributes. A retailer could test estimates of replenishment needs for a defined planning window. TabFM is not automatically a dedicated time-series forecasting method: promotions, seasonality, stock constraints and future feature availability still matter. Evaluate the cost of underestimation and overestimation separately.
An average error can hide serious failures on large orders or seasonal peaks. Inspect performance by region, product family and value band. If a planning team cannot explain what actions will change because of the prediction, the pilot is premature.
3. Sales and service triage
A sales team could test whether structured CRM fields predict conversion categories. A service operation might classify tickets into a small number of handling groups using historical records with reviewed labels. Both require clear label definitions, a documented review process and safeguards against unfair or inappropriate proxy variables.
Actiknow’s guide to sales pipeline forecasting from CRM data explains why stage hygiene, historical conversion rates and finance reconciliation must come before more complex models. The same principle applies to TabFM: unreliable source data produces unreliable evidence even when the inference step is convenient.
4. Finance exception review
A finance team could rank invoices or reconciliation records for human inspection based on historical exception outcomes. This is a triage application, not a replacement for financial controls. Evaluate false negatives, false alarms, reviewer capacity and auditability. High-risk decisions should remain governed by the organization’s existing approval and escalation requirements.
These are illustrative applications, not claims that Actiknow has delivered particular TabFM projects or achieved particular performance improvements. Each scenario requires its own data audit, baseline and controlled measurement.
How to use TabFM in BigQuery SQL
Google’s AI.PREDICT syntax takes two inputs: labeled context rows and prediction rows. The optional label_col argument names the target when the column is not called label. Numeric labels lead to regression output; STRING and BOOL labels lead to classification output. The prediction input must contain the feature columns used in the labeled context.
Current official documentation supports STRING, BOOL, INT64, FLOAT64, NUMERIC and BIGNUMERIC feature and label types. The AI.PREDICT reference currently lists up to 50 feature columns and up to 10 categories for classification. These are Preview-era documented constraints, so architects should recheck them before finalizing a design.
Illustrative classification SQL
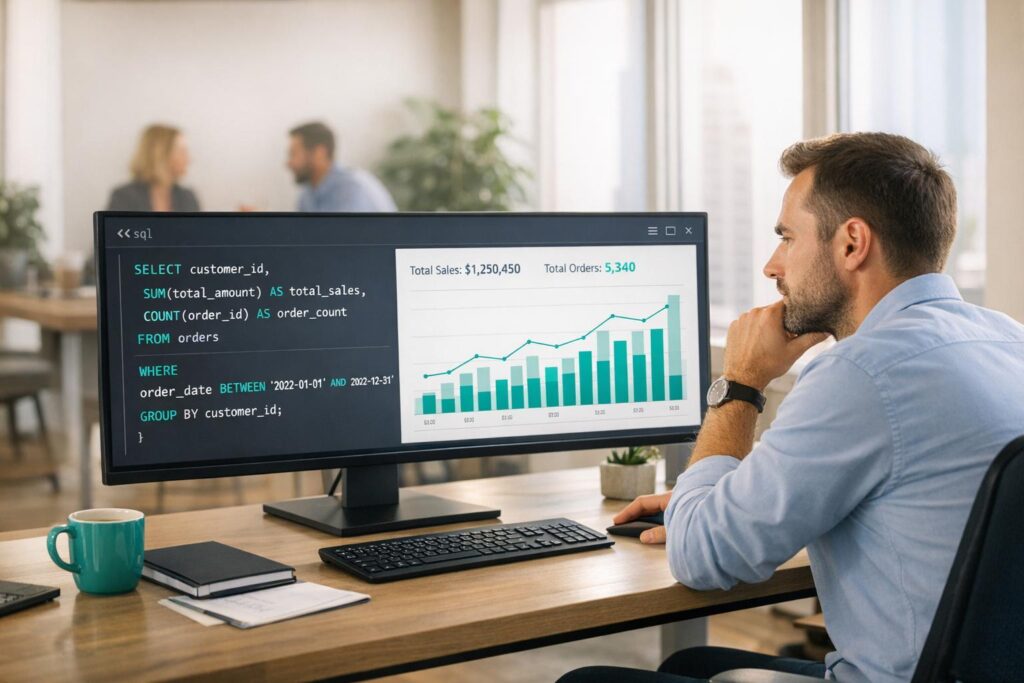
Suppose a prepared historical table contains renewal outcomes and a separate table contains accounts to score. The following SQL shows the pattern, not a query tested on a real client dataset. Replace the example project, dataset, fields and tables with approved production objects.
SELECT *
FROM AI.PREDICT(
(SELECT tenure_months, active_users_30d, tickets_90d,
plan_tier, renewal_outcome
FROM `project.analytics.historical_accounts`),
(SELECT tenure_months, active_users_30d, tickets_90d,
plan_tier
FROM `project.analytics.accounts_to_score`),
label_col => ‘renewal_outcome’
);
For a STRING label, BigQuery returns a predicted label and an array of label probabilities. Those probabilities are model outputs to evaluate and, if necessary, calibrate. They are not a contractual guarantee that a particular event will happen. Preserve the record identifier, input snapshot, SQL version and scoring time so results can be reviewed later.
Evaluation is not optional
Use AI.EVALUATE with labeled held-out data, and compare results with a simple baseline. For time-dependent business processes, prefer a time-based holdout over a purely random split. A random split can allow related accounts, later snapshots or future information to contaminate the evaluation.
An illustrative evaluation query is:
SELECT *
FROM AI.EVALUATE(
(SELECT tenure_months, active_users_30d, tickets_90d,
plan_tier, renewal_outcome
FROM `project.analytics.historical_accounts`
WHERE snapshot_date < DATE ‘2026-07-01’),
(SELECT tenure_months, active_users_30d, tickets_90d,
plan_tier, renewal_outcome
FROM `project.analytics.historical_accounts`
WHERE snapshot_date >= DATE ‘2026-07-01’
AND snapshot_date < DATE ‘2026-10-01’),
label_col => ‘renewal_outcome’
);
These SQL examples assume that the input feature columns were captured as of each snapshot date, the labels have matured and snapshot_date is used to select records rather than inadvertently supplied as a feature. Consult the official AI.PREDICT SQL reference and AI.EVALUATE documentation for exact signatures, return fields and regional availability.
A validation framework executives can trust
Define the decision before the metric
‘Predict churn’ is not a complete objective. ‘Identify up to 100 accounts for a weekly retention review using information available 30 days before renewal’ is testable. Document the decision owner, available capacity, action, expected cost and the outcome that would make the effort worthwhile. This turns a model experiment into a business experiment.
Choose a baseline that reflects the current operating method. It could be a rules-based risk flag, a historical conversion rate, a simple regression or the existing manual review queue. Record its accuracy and operational workload before introducing TabFM. If the new method does not improve the relevant outcome, novelty is not a reason to deploy it.
Build point-in-time-correct data
A data warehouse often stores the latest customer status, not the status that existed before an event. If a renewal decision was made in August, features from September should not be present in the August scoring row. Reconstruct historical snapshots or create them prospectively. Verify the label window, late-arriving updates, missing outcomes and repeated entity identifiers.
Separate context rows from holdout rows using a clear time boundary. Where practical, test several rolling periods, not one favorable split. Product launches, seasonality, pricing changes and shifts in customer composition can make a single historical period unrepresentative.
Measure errors in business terms
For classification, examine precision, recall, F1, confusion matrices, category prevalence and how different score thresholds affect the review queue. For regression, examine mean absolute error, median error, bias and the distribution of misses. Evaluate by region, product, customer size or other operationally meaningful cohorts.
A model that performs well overall can still be harmful if it systematically misses an important segment. If false negatives are expensive, measure the cost of missing them. If false positives consume scarce staff time, estimate that cost too. A single accuracy number cannot tell an executive whether the model should be trusted.
Distinguish prediction from intervention
A model can identify high-risk accounts without improving retention. If the team already contacts the same accounts, the incremental value may be close to zero. A controlled operational pilot should test whether the new ranking changes actions and outcomes. Prediction is also not causal inference: identifying a likely cancellation does not prove which offer will prevent it.
Ask the business owner to sign off on three things: the action that will change, the threshold for acceptable errors, and the evidence required to scale the pilot. Technical teams should not be left to define business risk by default.
Data engineering requirements that remain essential
Feature contracts and freshness
Create a feature contract that records source system, business definition, type, null handling, valid range, refresh cadence and availability at the decision date. Check for duplicate customers, unexpected category values, currency mismatches and source delays. A change in a CRM stage code or a web-event name can change predictions even if the SQL still runs successfully.
Do not fill the feature limit simply because it exists. A small set of stable, meaningful attributes is easier to govern and diagnose than a broad collection of poorly documented fields. Monitor missing values and distribution changes in every scheduled run.
Prediction logging and reproducibility
Store the input snapshot identifier, query version, run time, output scores, threshold used, downstream action and later observed outcome. Version-control the SQL that selects labeled context rows. Without this record, an organization may be unable to reproduce a score or explain why a specific case was prioritized.
Separate predicted indicators from audited KPIs. A dashboard should never display expected revenue as booked revenue or a predicted churn rate as observed churn. Actiknow’s BI dashboard services cover integrated reporting and executive dashboards, where that distinction between actual and estimated measures is critical to user trust.
Privacy, fairness and permissions
Use least-privileged access to approved BigQuery datasets. Review whether sensitive attributes or close proxies should be excluded, and test whether performance differs materially across relevant populations. Apply existing row- and column-level restrictions, retention policies and export controls. A warehouse-native function does not make every data use appropriate or compliant.
Because TabFM is in Preview, confirm organizational policies and Google Cloud’s Pre-GA terms before including regulated or sensitive information. Where possible, start with de-identified or synthetic records for feasibility checks, then obtain explicit approval before moving to real operational data.
Cost, performance and Preview constraints
Preview status is a production risk consideration, not merely a label. Google’s current TabFM documentation describes the feature under Pre-GA terms, with potentially limited support. Teams should verify availability, quotas, data residency, access requirements and support arrangements before making operational commitments.
The AI.PREDICT documentation describes early Preview billing through BigQuery slots for Enterprise and Enterprise Plus, or bytes processed for on-demand usage. It also announced a move to token-based TabFM charges from October 30, 2026, in addition to charges for the rest of the query. That date has passed. Check current Google Cloud pricing and the actual billed usage in your project rather than assuming the original Preview model still applies.
Total cost includes more than inference. Add the cost of scanning and preparing input tables, rerunning experiments, storing outputs, scheduling jobs, monitoring drift, investigating failures and reviewing cases. Set a pilot budget ceiling, cap inference volumes and track cost per scored record and per useful business action.
A scheduled experiment that starts with 5,000 accounts can become expensive if an upstream join unexpectedly multiplies rows. Include row-count checks, deduplication, bounded partitions and alerting. Query-level budgets and approval gates should be proportionate to the expected commercial value.
The current reference permits up to 50 feature columns and at most 10 classification categories. It specifies a limited set of scalar data types. Arbitrary nested objects, large unstructured text and high-cardinality identifiers require preparation; they are not evidence that every warehouse table is ready for direct inference.
TabFM versus conventional BigQuery ML
TabFM is worth considering when a team has labeled tabular data, a narrow question and a need for a quick SQL-based benchmark. Conventional trained models may be preferable when the organization requires greater control over hyperparameters, feature transformations, model versions, serving behavior, explainability or specialized evaluation.
For some business processes, a deterministic rule is better than any model. For others, a simple logistic regression or boosted tree is easier to understand and operate. For seasonal forecasts, a time-series approach may be more suitable. For high-stakes decisions, transparency and auditability can outweigh a modest improvement in aggregate prediction accuracy.
Compare alternatives using a consistent scorecard: quality on unseen periods, performance on important segments, cost per decision, engineering effort, monitoring burden and the impact of a wrong answer. The model with the highest headline metric is not always the system with the highest business value.
A practical four-week TabFM pilot
Week 1: Define the decision and audit data
Select one bounded use case. Define the label, prediction date, action, baseline, success threshold and decision owner. Review historical snapshots for leakage and data quality. Confirm access permissions and Preview suitability. Deliver a concise problem statement, feature contract and approved sample.
Week 2: Build reproducible queries and evaluate
Prepare version-controlled SQL, stable context and holdout sets, and a repeatable AI.PREDICT or AI.EVALUATE experiment. Calculate the baseline first. Capture model metrics, query duration, billing, data-quality exceptions and failure cases. Deliver an evaluation report that a business stakeholder can understand.
Week 3: Test edge cases and governance
Evaluate by segment and historical period. Test missing values, category drift, unexpected input growth, delayed source updates and failure handling. Review false positives and false negatives with the team that will use the predictions. Deliver a risk register, escalation workflow and cost controls.
Week 4: Run a controlled workflow and decide
Use the scores to inform a small, supervised operational process. Record which actions changed, the incremental outcomes, manual overrides and cost. Choose one of three explicit decisions: stop, extend the experiment or approve a limited production design with named ownership and rollback criteria.
Production acceptance checklist
A pilot is not production-ready because the SQL returns plausible results. Require a documented decision owner; point-in-time-correct features; representative labeled context; an untouched holdout; a baseline comparison; performance by critical segment; agreed error thresholds; approved data use; monitored cost and latency; an incident response path; and a tested rollback.
Once operational, monitor source freshness, records scored, output distribution, failures, cost, human overrides and the eventual ground-truth outcomes. Review model drift when labels mature. Pause automated downstream actions when a material input or output change cannot be explained.
Executives should ask five questions in each review: What decision changed? How many cases were affected? Did the change improve outcomes? What did it cost? What happened when the prediction was wrong? These questions prevent an impressive-looking predictive dashboard from becoming an unaccountable operating system.
Frequently asked questions
1. Is BigQuery TabFM generally available?
No. As of November 7, 2026, Google’s official TabFM and AI.PREDICT documentation still labels the feature Preview. Recheck the release notes before relying on production service levels or support commitments.
2. Does zero-shot prediction mean no historical data is needed?
No. The model is pretrained, so it does not require a task-specific training job, but AI.PREDICT still needs labeled historical rows as context. Missing labels, inconsistent outcomes and data leakage remain serious problems.
3. Can an analyst use TabFM without Python?
Yes. BigQuery exposes TabFM through SQL functions. That makes experimentation accessible to SQL-oriented analytics teams, although feature preparation, validation, access control and monitoring still require engineering discipline.
4. Does TabFM support both classification and regression?
Yes. Numeric target labels produce regression predictions, while STRING and BOOL targets produce classification predictions. The documented feature types and limits apply, so verify the schema before testing.
5. Is TabFM a replacement for BigQuery ML?
No. It is an additional option. Conventional supervised models can provide more tuning and deployment control, and may be cheaper or more accurate for a particular dataset. Compare them on the same held-out evidence.
6. Can it forecast next month’s sales?
It can estimate numerical outcomes from structured features, but it is not automatically a specialized time-series forecasting system. Seasonality, timing, promotions, inventory and the availability of future inputs require explicit modeling and validation.
7. How should performance be measured?
Use labeled holdout data, ideally from a later period for time-dependent processes. Compare with a simple baseline, inspect relevant segments and translate false positives and false negatives into the cost of real business actions.
8. What are the main documented limits?
The current AI.PREDICT reference specifies up to 50 feature columns, up to 10 classification categories and supported scalar data types. These are Preview-era limits and can change.
9. What should be monitored after deployment?
Monitor source freshness, feature distributions, score distributions, query failures, cost, review actions and eventual actual outcomes. Reevaluate whenever labels mature or the business process changes.
10. What should a CEO or CIO approve first?
Approve a narrow pilot with a named owner, clear decision, baseline, cost cap, privacy review and measurable success criteria. Do not authorize a broad predictive analytics rollout before one use case demonstrates practical value.
The executive takeaway
BigQuery TabFM lowers the barrier to testing whether existing warehouse data can support useful predictions. Its strongest near-term value is faster, SQL-based experimentation. It does not remove the need for reliable labels, point-in-time data, fair evaluation, cost discipline or accountable decisions. A pilot that disproves a weak use case quickly is as valuable as one that identifies a credible opportunity.
Discuss a focused predictive analytics pilot
If your organization has data in BigQuery but needs help defining trustworthy KPIs, integrating source systems, preparing historical features or presenting predictions responsibly, Actiknow can discuss the underlying BI and data architecture. Contact Actiknow to scope a limited discovery conversation around one measurable business decision rather than a broad technology purchase.
Sources and further reading
- Google Cloud: BigQuery release notes, August 31, 2026 TabFM Preview announcement.
- Google Cloud: The TabFM model, official product guide.
- Google Cloud: AI.PREDICT and AI.EVALUATE function references, including SQL syntax, outputs and documented limits.
- Google Cloud: BigQuery ML model evaluation overview for supervised-model evaluation principles.