
The real risk is not rerunning data. It is changing what the business trusts.
A finance dashboard reports one number for last quarter. A source-system correction reveals that several transactions were assigned to the wrong month. Engineering can fix the data, but the repair touches historical partitions, incremental transformations, aggregates and dashboards that executives use every morning. If the team simply reruns the pipeline, it may duplicate records, overwrite newer changes, exhaust warehouse capacity or expose inconsistent totals halfway through the process.
A backfill is a controlled reprocessing of previously processed data. It may be needed after a source correction, missed ingestion, mapping defect, changed business rule, late-arriving event or migration. A sound data pipeline backfill strategy treats this as a governed change to production information, not a one-off batch job. The objective is to restore the correct historical state while preserving the reliability and availability of current reporting.
The operating principle is straightforward: define the intended correction, isolate its scope, replay deterministically, validate against an agreed source of truth, then publish the corrected result in a controlled way. Each step needs evidence, an owner and a way to stop.
1. Diagnose the defect before selecting a date range
Start with the business discrepancy. Which metric is wrong? Which source and transformation created it? Is the error limited to a particular account, region, event type or period? When did the defective logic first run? A backfill of all historical data may appear safer, but it increases cost, runtime and blast radius without necessarily addressing the cause.
Create a backfill contract containing: the affected datasets and downstream consumers; the exact source of truth; business keys and event-time boundaries; whether the repair corrects inserts, updates or deletes; expected changes to key totals; the intended publication window; accountable approvers; and the rollback method. Record both event time and ingestion or processing time. A transaction dated March may have been corrected in October, so filtering only by March ingestion timestamps will miss it.
For example, if a tax calculation was wrong only for orders from one country between 1 April and 15 May, the replay scope should ordinarily include those orders plus any dependent aggregate windows, rather than every order in the warehouse. Validate whether joins, cumulative balances, attribution windows or slowly changing dimensions extend the impact beyond that interval.
2. Map dependencies in the order they actually execute
A typical flow is source extraction → raw landing → standardized records → dimensional models → aggregates → semantic metrics → dashboards and exports. A corrected raw row does not automatically repair every downstream materialization. A daily revenue table may be rebuilt from order facts, while a monthly cumulative measure depends on all subsequent periods.
Build a dependency graph and mark each node as immutable, replaceable, incremental, snapshot-based or externally published. Identify the earliest safe replay boundary for each node. If a customer dimension changed its historical assignment, fact rows may need to be rejoined. If a rolling 30-day measure changes on 10 June, dates through early July may need recalculation. For cumulative balances, the downstream recomputation horizon can be much longer.
Keep current-day ingestion on a separate operational lane where feasible. Separate orchestration queues, warehouse resource groups or concurrency limits prevent a heavy historical replay from starving routine freshness-critical work. Never assume that a task scheduler’s retry behavior alone provides isolation.
3. Design for idempotency and deterministic results
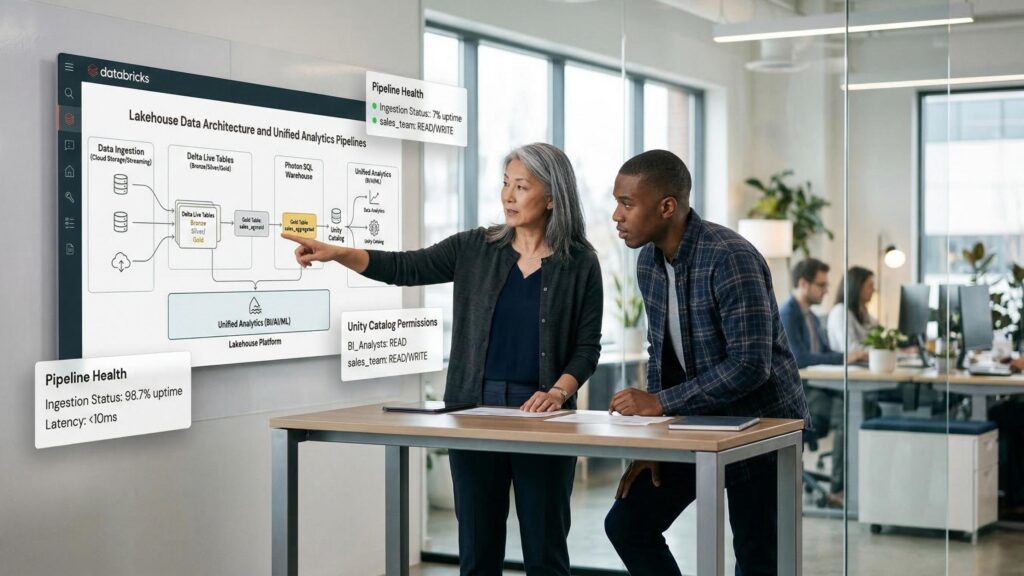
An idempotent backfill can be rerun without producing additional duplicates or changing a correct result unexpectedly. The implementation should use stable business keys, explicit partition boundaries, reproducible transformation versions and controlled write semantics. Append-only inserts into final tables are usually unsafe when historical rows already exist.
For partitioned tables, a common approach is to calculate the complete replacement partition in staging, validate it and then atomically swap or replace that partition where the platform supports such operations. For row-level corrections, use a well-defined MERGE keyed on the business identity, with delete handling and deduplication rules. Some engines implement MERGE differently; test actual transactional and concurrency guarantees rather than assuming all warehouses behave alike.
Illustrative SQL pattern (adapt to your warehouse and table design):
MERGE INTO mart.orders AS target
USING staging.corrected_orders AS source
ON target.order_id = source.order_id
WHEN MATCHED THEN UPDATE SET
order_date = source.order_date,
net_amount = source.net_amount,
updated_at = source.updated_at
WHEN NOT MATCHED THEN INSERT
(order_id, order_date, net_amount, updated_at)
VALUES (source.order_id, source.order_date, source.net_amount, source.updated_at);
This example does not delete records removed from the source, protect against duplicate source keys or handle concurrent updates. Production designs need explicit policies for all three. Before a MERGE, enforce one source row per business key and confirm that the replay is using the correct version of each record. If the source uses change-data-capture events, replay order, tombstones and sequence numbers matter.
Store a run identifier, code version, input snapshot or watermark, scoped date range, counts and checksums. These details make a rerun explainable. Avoid replaying from a mutable API without preserving the input snapshot when the API may return different results later.
4. Choose a replay method that fits the failure
Partition replacement
Best when an entire bounded day, month or partition can be recomputed from complete source data. It is easy to reason about and compare, but requires enough compute and storage to rebuild the whole partition. It can be risky if the partition contains valid recent corrections that the replay source does not include.
Key-based correction
Best when a small, identifiable set of records changed. It limits processing volume but demands reliable keys, deduplication and delete handling. Downstream aggregates still need recalculation.
Full historical rebuild
Appropriate when a foundational business rule or dimension invalidates most historical output, or when incremental repair cannot be trusted. Rebuild into a parallel environment when possible, compare results and switch readers only after approval. Do not use a full rebuild merely because it is simpler to script.
CDC replay or event-log replay
Useful when an ordered, retained change log exists and consumers can reconstruct state deterministically. Verify retention limits, schema evolution, event ordering and exactly-once assumptions. Exactly-once delivery claims do not automatically mean exactly-once business outcomes.
5. Protect today’s reports with a staged publication model
The safest default for business-critical reporting is to keep corrected output out of production until validation passes. Create isolated staging or shadow tables, compute the corrected slice, and compare it to both the source and the current published slice. If the warehouse supports atomic swaps, transactional replacements or versioned views, publish the validated dataset as a single controlled change. Otherwise use a documented maintenance window and communicate the temporary inconsistency risk.
A dashboard can be technically available yet analytically wrong if its fact table has been corrected but its aggregate cache has not. Coordinate cache invalidation, extract refreshes, semantic-model refreshes and downstream exports with the publication step. Treat customer-facing APIs and scheduled files as downstream consumers too.
For high-stakes financial reporting, define whether historical periods are permitted to change automatically. Some organizations need a restatement process with revised period labels and approval, not silent replacement of previously issued figures. Maintain an audit record of what changed, why and who authorized it.
6. Validate the correction at multiple levels
Row counts alone are insufficient. A backfill can preserve the number of rows while changing every amount incorrectly. Validation should compare source and target at a consistent snapshot and business grain, including: completeness, uniqueness, null and referential-integrity checks, business totals, affected keys, unchanged control populations, and downstream KPI behavior.
A practical validation package contains four comparisons. First, the affected population: expected versus actual keys, record counts and missing or extra rows. Second, values: financial totals, quantities, statuses and other business-specific measures. Third, unaffected controls: adjacent dates, unrelated regions and known stable customers should not drift. Fourth, consumer outputs: sample dashboards and exports must reflect the approved change.
Use explicit tolerance rules. Zero tolerance is often appropriate for identifiers, duplicates and exact financial ledger totals. Small numeric tolerances may be justified for floating-point calculations, currency conversion or rounding, but must be approved before the run, not invented after seeing discrepancies. For any exception, record its owner, reason, amount, disposition and approval.
Example reconciliation query for a bounded interval:
SELECT order_date,
COUNT(*) AS order_count,
SUM(net_amount) AS net_revenue
FROM staging.corrected_orders
WHERE order_date >= DATE ‘2026-04-01’
AND order_date < DATE ‘2026-05-16’
GROUP BY order_date
ORDER BY order_date;
Compare the same grain and business filters with the authoritative source and the proposed production replacement. Normalize timezone, currency, tax inclusion, cancellation rules and cutoff definitions before treating differences as defects.
7. Control resource consumption and operational risk
Historical reprocessing competes with scheduled ingestion, interactive BI queries and other transformations. Estimate scanned bytes, output volume, partition count, run duration, temporary storage and peak concurrency using a representative pilot. Put explicit bounds on execution time, batch size, retries and cost. A backfill that repeatedly retries a malformed partition can consume substantial resources without progress.
Run small batches with checkpoints. Monitor freshness lag for current pipelines, query latency for critical reports, warehouse utilization, error rates and unexpected growth in output tables. Define stop conditions before starting: for example, freshness exceeds its SLA, validation error exceeds the agreed threshold, a protected workload degrades, or spend reaches the approved cap. Stop conditions must have an operator who can act.
Avoid the trap of launching all historical partitions in parallel. More concurrency may increase contention rather than throughput, especially when the replay hits the same source API or writes to overlapping target partitions. Test a small partition, then scale deliberately.
8. Make rollback and recovery concrete
Rollback is not simply rerunning yesterday’s code. If corrected records have already reached dashboards, exports or third-party systems, recovery may involve restoring a prior table version, reverting a view pointer, rebuilding dependent aggregates and notifying consumers of the restored figures.
Before publication, retain a recoverable version of the affected output or a validated snapshot, subject to retention and privacy requirements. Document the rollback trigger, execution steps, owner, expected recovery time and whether current-day writes continue during restoration. Test this path in a lower environment. A plan that has never been exercised is an assumption.
Where downstream consumers cannot be rolled back atomically, prefer versioned datasets and explicit cutover markers. Keep a change log that links the incident, source correction, code revision, replay run, validation evidence and business approval.
9. A practical four-week implementation plan
Week 1: Define the correction contract
Inventory affected models and reports; identify authoritative sources, impacted business keys and dates; capture baseline metrics; assign engineering, analytics and business owners. Agree on acceptable variance, maintenance windows and communication requirements. Deliverable: approved scope and dependency map.
Week 2: Build the isolated replay
Implement deterministic extraction, staging, idempotent writes, checkpointing and audit logs. Test duplicates, deletes, late events, failed batches and reruns. Benchmark one representative historical slice. Deliverable: repeatable backfill procedure with measured resource requirements.
Week 3: Validate and rehearse
Recompute dependent models, compare source-to-target totals, inspect dashboard outputs and execute a rollback rehearsal. Confirm current ingestion remains within freshness targets during the pilot. Deliverable: signed reconciliation report and go/no-go criteria.
Week 4: Release and monitor
Run in approved batches, monitor stop conditions, publish through the agreed cutover method, refresh consumers and communicate revised figures. Keep heightened monitoring until normal freshness and KPI reconciliation stabilize. Deliverable: completion evidence, exception log and post-incident improvements.
10. Executive acceptance checklist
A backfill is ready for production when the team can answer yes to all of these questions:
- Do we know exactly which business results are wrong?
- Can we reproduce the intended input state?
- Is the affected downstream dependency chain mapped?
- Can the replay be safely repeated?
- Are deletes and late corrections handled?
- Is the new output isolated until approval?
- Have both affected and unaffected populations been tested?
- Are costs and current-day service levels protected?
- Can we restore the previous published state?
- Has the business owner approved the revised numbers?
If any answer is unknown, the next step is not necessarily to cancel the repair. It is to reduce the scope, add evidence or schedule a controlled rehearsal before exposing changes to production users.
Frequently asked questions
What is a data pipeline backfill?
It is the controlled reprocessing or reconstruction of historical data to correct gaps, errors or changed logic. It can affect raw, transformed and reporting layers.
How is a backfill different from a routine incremental load?
An incremental load normally processes newly arrived or recently changed data. A backfill deliberately revisits older data and must account for already published results and downstream dependencies.
Should we stop daily pipelines during a backfill?
Not automatically. Separate resources and write boundaries when possible. Pause or coordinate specific jobs only if they would conflict with the replay or compromise consistency.
How far back should we reprocess?
Use the earliest affected event and the full dependency horizon, including rolling windows, cumulative measures and dimension changes. The defect’s date range alone may be insufficient.
Can we just delete the old rows and reload?
Only when the deletion and reload are safely isolated and the source is complete. Otherwise readers may see gaps, valid updates may be lost and downstream models may remain stale.
What makes a backfill idempotent?
Stable keys, deterministic inputs and transformations, controlled replacement or merge behavior, and explicit handling of duplicates and deletes. Running the same correction twice should not double-count it.
How do we prove the result is correct?
Compare source and target using agreed snapshots, keys, totals and business definitions, then validate downstream KPIs and unchanged control populations.
What if the source system changed after the incident?
Use a preserved snapshot or reconstruct the correct state from an ordered change history. If neither exists, document the uncertainty and obtain business approval for the reconciliation approach.
Does a warehouse transaction make a backfill safe?
Transactions help protect a particular write boundary. They do not automatically coordinate external APIs, BI caches, extracts, downstream jobs or business sign-offs.
How should we communicate revised historical KPIs?
Explain which periods and measures changed, the reason, the effective publication time, the size of the restatement and whom to contact. Finance-controlled metrics may require formal approval.
When is a full rebuild preferable?
When the defect is pervasive, incremental dependencies are not trustworthy or rebuilding in parallel is simpler and safer than selective repair. Validate capacity and cutover before committing.
Who owns backfill approval?
Engineering owns technical execution and recovery. Data or analytics owners validate model behavior. The accountable business owner approves material changes to reported figures.
The decision that matters
A reliable backfill is measured not by how quickly old partitions were processed but by whether the organization can explain and trust the corrected numbers while current reporting continues. The best design minimizes blast radius, makes replay repeatable, validates the entire dependency chain and provides a controlled path to publish or reverse the change.
For organizations reviewing data integration and reporting reliability, Actiknow’s business intelligence consulting and implementation services can help frame the data-flow, modeling and validation work. If you are planning a historical data correction or rebuilding reporting pipelines, contact Actiknow to discuss the scope and operational requirements.