
Audience: CIOs, CTOs, COOs, enterprise architects and business leaders responsible for integrating SaaS, ERP, CRM and proprietary systems.
The decision is not simply whether to buy software or write code
A sales order starts in a customer portal, is validated against pricing rules, enters an ERP, reserves inventory, triggers fulfillment and eventually becomes an invoice. Every handoff depends on integration. When a process breaks, the customer does not care whether the failure occurred in a visual workflow or a custom service. The business owns the outcome.
An integration platform as a service (iPaaS) can accelerate connections between common applications. Custom middleware can offer tighter control over proprietary rules, performance, security boundaries and operational behavior. Neither automatically solves inconsistent master data, unclear process ownership or missing reconciliation.
The executive question is more precise: which capabilities should we purchase as a managed service, which should we control as business assets, and who will be accountable for the result over the next three to five years?
This article focuses on the ownership and economics of that decision. For a broader comparison of direct APIs, iPaaS and a reusable integration layer, see Actiknow’s guide to SaaS integration architecture.
Define the two options without confusing the categories
What an iPaaS typically provides
An iPaaS is a managed environment for designing, executing and observing integrations. Depending on the product and tier, it may include prebuilt connectors, visual mapping, scheduling, API endpoints, workflow orchestration, authentication support, retry policies, execution histories and deployment controls. The vendor operates significant portions of the platform infrastructure; your organization still owns its data contracts, business decisions, credentials, access rules and production processes.
Prebuilt does not mean zero maintenance. Connectors can have unsupported endpoints, limited field coverage, vendor-specific data models, changing authentication requirements or delayed support for new API versions. A connector that can read customers may not support the exact write or bulk operation your process needs.
What custom middleware actually means
Custom middleware is software your organization commissions or develops to mediate systems. It may be a small service that normalizes customer records, an API facade around an ERP, a queue-backed order processor, or a collection of reusable integration services. It can use managed cloud infrastructure and third-party libraries; custom does not imply building every component from scratch.
The distinction is ownership of the integration behavior. Your team controls code, contracts, release cadence and failure handling, but also inherits responsibility for security patches, dependency upgrades, runtime reliability, deployment pipelines, documentation and on-call support.
Actiknow’s custom solutions practice explicitly covers API-based system integration, business automation and tailored applications. That makes custom middleware a plausible delivery option, not a default recommendation for every integration.
Start with the business process, not the connector catalog
A connector list is a poor architecture brief. Document the business events that must be correct: customer created, order accepted, payment settled, employee onboarded, product price changed, subscription cancelled. For each event, identify the authoritative system, downstream consumers, allowed delay, permissible data loss, duplicate risk and manual recovery procedure.
Consider an order confirmation. If the portal tells a buyer that an order was accepted, what happens when the ERP is temporarily unavailable? The answer may require a durable queue, a unique order identifier, an explicit pending state and a reconciliation job. Those requirements exist regardless of platform choice.
For a nightly marketing contact refresh, an hour of delay may be tolerable and a managed connector may be sufficient. For inventory reservations, a stale or duplicate update may directly affect fulfillment. Business criticality, not technology fashion, should determine the engineering investment.
Seven dimensions that should drive the build-or-buy decision
1. Connector coverage and the real speed to production
iPaaS has an advantage when the source and destination are mainstream applications, required operations are supported and transformation logic is modest. A vendor-maintained connector can reduce authentication, pagination and basic API maintenance work.
Test coverage at the operation level: read, create, update, delete, bulk export, webhook subscription, custom fields, pagination and tenant-specific permissions. Require a proof of concept using actual edge cases, not a demonstration that two products appear in a catalog.
Custom middleware is often more appropriate when a proprietary ERP, unusual protocol, legacy database or specialized vendor API is central to the workflow. Even then, use mature SDKs or managed services where they reduce undifferentiated effort.
2. Ownership of proprietary business logic
A workflow that copies a contact from one system to another is not usually strategic intellectual property. A pricing eligibility engine that combines customer agreements, geography, credit status, inventory and approval authority may be. Embedding such rules inside dozens of vendor-specific visual workflows can make them difficult to test, audit, reuse and move.
A practical boundary is to keep commodity transport and mapping in a managed platform while exposing proprietary decisions through a versioned internal API. The iPaaS calls the business service; it does not become the permanent home of the business rule. This preserves a single source of logic across portals, mobile apps, batch jobs and integrations.
3. Observability and failure recovery
Ask how support can answer a concrete question: Why did order 78421 reach the CRM but not the ERP? A useful system should correlate source ID, workflow execution, transformation version, target request, error classification, retry attempts and final business state.
Some iPaaS products provide excellent run histories and alerts. Others require premium tiers or separate logging to achieve end-to-end traceability. Custom middleware can be instrumented to your standards, but only if observability is funded and implemented. A custom script with a success email is not an observability strategy.
For critical flows, require durable processing records, bounded retries, dead-letter handling, replay with authorization, reconciliation against the source of truth and measurable end-to-end lag. Actiknow’s article on reliable API integrations explains why rate limits, idempotency, webhooks and replay must be treated as production design requirements.
4. Performance, latency and throughput
Do not assume custom code is faster or iPaaS is slower. Benchmark the specific workload. A platform may batch efficiently, while an improvised custom service may serialize requests unnecessarily. Conversely, a platform’s execution quotas or per-step overhead may be unsuitable for very high-volume or low-latency processing.
Estimate peak events per minute, average payload, burst duration, source API quotas, retry amplification, target write limits and required recovery time after an outage. A flow that processes 50,000 events on a normal day but must absorb 500,000 after downtime has a different capacity problem from one with a steady 35 events per minute.
Where interactive response time matters, consider whether the business action should be synchronous at all. An asynchronous acceptance-and-status model may be safer than forcing a customer request to wait on three external vendors.
5. Security, residency and compliance boundaries
Identify where payloads travel, which systems persist them, how long execution logs retain them, who can view them and which credentials can perform writes. Review the platform’s hosting regions, subprocessors, encryption, access controls, audit trails and incident response terms against your own obligations.
Custom middleware may offer more control over network placement and retention, but it does not automatically offer better security. Your team must implement secrets management, least privilege, token rotation, vulnerability management, audit logging and secure operations. The right choice depends on the actual controls and accountable teams, not on a general claim that one model is more secure.
6. Change management and vendor dependence
An iPaaS introduces a vendor dependency in workflow definitions, connectors, deployment tooling and potentially proprietary mapping expressions. Custom middleware introduces dependency on internal developers, libraries, cloud infrastructure and undocumented design decisions. Both can lock an organization in, but through different mechanisms.
Reduce avoidable dependence with explicit data contracts, portable business rules, source-controlled configuration where supported, automated regression tests, documented field mappings and an inventory of every production flow. Before signing a contract, ask how workflows, execution logs and mappings can be exported and how a migration would work.
7. The capability to operate what you build
A custom integration service is a product, even if no customer sees it. It needs an owner, backlog, service-level objectives, change approval, testing, incident response, documentation and budget. If the organization cannot provide those, buying managed capabilities may reduce operational risk.
The reverse is also true: a visual integration platform still needs disciplined owners. Citizen-developed flows without review can multiply credentials, duplicate transformations and create invisible business dependencies. Buying a platform does not eliminate engineering governance.
Compare total cost of ownership, not the first-year invoice
A fair comparison covers implementation, ongoing operations, variable usage, expected change and exit costs. For iPaaS, model subscription tiers, connector premiums, executions or tasks, data volume, environments, support, monitoring, overage charges and the people needed to administer workflows. For custom middleware, model discovery, development, cloud infrastructure, monitoring, security, testing, support coverage, upgrades, incident response and replacement of key personnel.
Use the same time horizon and workload assumptions. Treat the value of faster delivery and avoided business interruption as benefits only when you can justify them. Do not compare a fully supported platform subscription against the salary cost of one developer who is assumed to be available indefinitely.
An illustrative three-year comparison
Suppose an organization is evaluating ten integrations. For illustration only, assume the managed platform costs $36,000 annually, needs $25,000 in initial configuration and $18,000 annually in internal support. Its three-year cash cost would be $25,000 + 3 × ($36,000 + $18,000) = $187,000 before overages or expansion.
Assume the custom alternative costs $95,000 to build, $14,000 annually in cloud and tools, and $45,000 annually in engineering support. Its three-year cash cost would be $95,000 + 3 × ($14,000 + $45,000) = $272,000. Under these hypothetical inputs, iPaaS is $85,000 less expensive. This is arithmetic, not a market quote, case study or forecast.
Now change the assumptions. If event volume pushes the platform into a much higher usage tier, or if the custom service can be reused by twenty additional workflows, the comparison may change. Equally, a security incident or an unstaffed custom service can erase apparent savings. Run low, expected and high-volume scenarios, then perform sensitivity analysis on support effort and change frequency.
The cost of change is often the deciding variable
Track how many hours a routine API change, new business field or new destination requires. The important question is not just the initial cost per integration, but the marginal cost of the next ten integrations and the cost of keeping the existing ten correct. Reuse is valuable only when teams actually use the shared capability.
A practical decision matrix for executives
Favor iPaaS when connectors are mature, the process is standardized, latency and throughput fit the platform, business rules are limited, the organization values faster rollout and the managed operating model is attractive. Favor custom middleware when proprietary rules dominate, unsupported interfaces are critical, special performance or network requirements exist, and there is an accountable team able to operate the software.
Favor a hybrid when common SaaS connections can be delegated to a platform but domain-specific decisions should remain behind owned APIs. Do not use a hybrid merely to avoid choosing. Define the boundary explicitly: transport and scheduling on one side, canonical contracts and strategic business decisions on the other.
A useful scoring exercise assigns each candidate workflow a score from one to five for connector fit, business-rule uniqueness, failure impact, throughput complexity, data sensitivity, rate of change and internal support capacity. Weight failure impact and support capacity more heavily than a minor difference in implementation speed. Scores support discussion; they should not replace architecture testing.
What a hybrid architecture looks like in practice
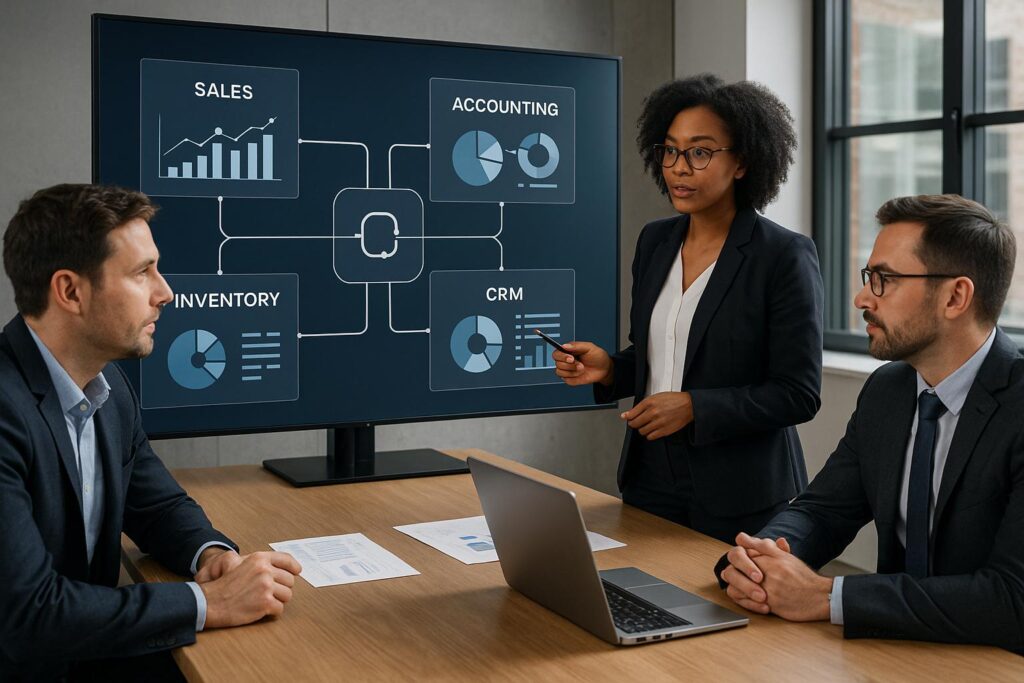
Imagine a business connecting CRM, billing, ERP, customer portal and analytics systems. A managed integration platform handles scheduled contact synchronization, standard invoice notifications and routine marketing updates. A small internal customer service exposes a canonical customer ID, validation rules and permitted account transitions. An order service owns order acceptance and idempotent processing. A warehouse pipeline receives analytical copies of events without becoming the operational system of record.
The platform orchestrates routine transfers, while the internal services preserve proprietary behavior. Each flow records a correlation ID and business outcome. A reconciliation job checks that accepted orders reach the ERP, and a support queue surfaces exceptions that need human decisions. The architecture remains understandable because responsibility is assigned by business capability rather than by tool.
This is a hypothetical architecture pattern, not a claim about a specific Actiknow client implementation. For analytics-specific source and destination connections, Actiknow’s connectors offering describes integrations across SaaS platforms and cloud data destinations.
Non-negotiable requirements for either option
A contract for every important interface
Record source and target systems, schema, field meanings, identifiers, event semantics, authoritative owner, transformation version, expected frequency, permissible lag and deletion behavior. Explicitly distinguish missing values from intentional clearing of values. Define how schema changes are introduced and tested.
Idempotency and reconciliation
Retries are inevitable. For writes, use a stable business key or vendor-supported idempotency key where possible. Where exactly-once business outcomes cannot be guaranteed by the transport, build deduplication and reconciliation. Compare source and target counts or control totals where meaningful; investigate exceptions rather than assuming a green workflow means complete data.
Operational access and incident response
Specify who can pause, replay, deploy, rotate secrets and approve exceptional changes. Separate development, test and production environments where practical. Document failure scenarios: expired OAuth tokens, rate limiting, duplicate webhook deliveries, target downtime, malformed payloads and a bad deployment. Test recovery before a real incident.
A usable support ledger
For each critical item, retain the business ID, source ID, workflow version, correlation ID, timestamps, attempt count, final state and safe error context for an appropriate period. Restrict sensitive payloads and establish retention rules. Support should be able to find a failed order without asking an engineer to search several disconnected logs.
A 60-day evaluation and implementation plan
Days 1–10: inventory and prioritize
List current integrations, their owners, business processes, volumes, failure histories, data classifications, vendor contracts and support costs. Identify the three workflows where a failure creates the greatest operational damage. Baseline incident count, time to detect, time to recover, manual corrections and average integration change lead time.
Days 11–20: define decision criteria and costs
Document required operations for each connector, failure semantics, security boundaries, latency targets, portability requirements and a three-year cost model. Shortlist realistic platform and custom designs. Identify the person or team that will own each option in production.
Days 21–35: run a representative proof of concept
Choose one simple SaaS flow and one difficult flow with real transformations or exceptions. Test normal processing, a malformed record, API throttling, duplicate delivery, partial outage, replay and a schema change. Record implementation time and operational effort, not just whether the happy path works.
Days 36–45: review the operating model
Validate security and access controls, deployment and rollback, incident runbooks, vendor support response, monitoring coverage and contract exit terms. Ask a support engineer who did not build the prototype to diagnose a deliberately introduced failure. This is a stronger test than a polished demonstration.
Days 46–60: decide boundaries and stage rollout
Approve an architecture decision record that states which integration capabilities will be bought, which will be owned, why, and when the decision should be revisited. Migrate or implement the first production flow with reconciliation and a rollback plan. Assign service ownership and publish a small set of operational metrics.
Metrics the leadership team should review
Measure business outcomes as well as platform health: percentage of critical events processed within the required time, unreconciled record count, number of duplicate business actions, mean time to detect and recover, exception backlog age, changes deployed without incident, integration cost per meaningful business event and percentage of flows with named owners. Raw execution counts can be useful for billing, but they are not a substitute for business correctness.
Review these metrics by workflow criticality. A late marketing update and a duplicated payment should not be combined into one undifferentiated success percentage. Escalate unresolved reconciliation failures even when the integration tool reports that its jobs completed successfully.
Common mistakes that make either choice expensive
- Buying on connector count alone: a catalog entry may not support required operations or service limits.
- Building a custom platform too early: a team spends months creating a framework for five straightforward workflows.
- Putting strategic rules into opaque mappings: business behavior becomes difficult to audit and reuse.
- Ignoring support ownership: production incidents depend on the one person who remembers the integration.
- Treating workflow success as data correctness: partial records and duplicates pass unnoticed.
- Neglecting exit planning: vendor-specific transformations or undocumented code make change prohibitively costly.
The common thread is confusing the integration mechanism with the operating model. Good governance is neither an iPaaS feature checkbox nor a benefit that appears automatically when code is owned.
Frequently asked questions
Is iPaaS always cheaper than custom middleware?
No. It may lower initial delivery and infrastructure effort, particularly for standard SaaS workflows. Variable pricing, connector premiums, specialized transformations and long-term support can change the economics. Compare three-year scenarios with identical workloads and service requirements.
When should a company build its own integration layer?
When it has recurring, valuable integration requirements that cannot be served economically or reliably by managed tools, and when it can fund a long-term engineering owner. Reuse, proprietary business rules, difficult interfaces and operational control are stronger reasons than a general desire to own code.
Can we use an iPaaS and custom middleware together?
Yes. A managed platform can handle common connectors and scheduling while internal APIs own proprietary decisions and canonical contracts. Define the handoff, monitoring, security and failure responsibility so the hybrid does not become two uncoordinated systems.
What is the difference between middleware and an API gateway?
An API gateway commonly manages entry-point concerns such as routing, authentication, throttling and policy enforcement. Middleware may also transform data, orchestrate workflows, persist state, manage retries and coordinate multiple systems. A gateway can be part of an integration architecture but does not by itself replace all middleware behavior.
Does low-code mean business users can own production integrations?
Some workflows can be maintained by trained operations teams, but production ownership still requires access controls, change review, testing, monitoring and escalation. Complex exception handling or sensitive financial workflows may require engineering oversight regardless of the design interface.
How should we handle vendor lock-in?
Separate business rules from platform-specific workflows, document contracts and mappings, maintain exportable configuration where supported, and test how a representative flow would be migrated. Also recognize that custom code can create dependence on individuals and libraries.
Should integrations send data through the warehouse?
Use the warehouse for analytical integration and reporting where appropriate. Operational commands such as accepting an order or reserving inventory generally need an application-level contract and business-state handling, rather than relying on a warehouse as an operational message broker.
What should be included in an integration platform proof of concept?
Include representative volumes, custom fields, real authorization, duplicate events, retries, partial failures, schema changes, reconciliation, monitoring, deployment and support diagnosis. Measure both time to build and time to recover.
Conclusion: own the decisions that differentiate your business
Most organizations do not need to own every connector, scheduler and transport mechanism. They do need clear ownership of business rules, data contracts, security obligations and operational outcomes. The right architecture may be managed, custom or hybrid, and it may change as the integration estate grows.
If you are deciding between an integration platform and custom middleware, Actiknow can help assess the existing interfaces, clarify the operating requirements and design an implementation path through its integration and custom application services. Contact Actiknow to discuss a focused architecture review rather than committing to a platform before the requirements are clear.