Revenue reporting does not become trustworthy because a dashboard refreshes successfully
A revenue dashboard can be technically healthy and still be wrong.
The pipeline may complete. The warehouse may be online. Power BI or Tableau may refresh without errors. Yet yesterday’s opportunities may be missing, a duplicate order may inflate bookings, an exchange rate may be stale, or a source-system change may silently alter how a critical field is populated.
This is why data quality monitoring must be designed separately from infrastructure monitoring.
Infrastructure monitoring asks whether the system ran.
Data quality monitoring asks whether the resulting data is complete, current, internally consistent, and reconcilable to the business systems that matter.
For revenue reporting, that distinction is especially important because executives often make decisions from a small number of high-impact metrics: bookings, revenue, pipeline, renewals, average deal size, conversion, collections or forecast. A technically successful pipeline that produces the wrong number is more dangerous than a failed pipeline that visibly alerts the team.
Actiknow’s business intelligence services span data integration, architecture, dashboards, publishing and refresh mechanisms. That full reporting path is the right scope for data-quality controls because quality failures can originate at any point between the operational source and the executive dashboard.
1. Start with the revenue metrics that matter
Do not begin by writing hundreds of generic tests across every warehouse column.
Start with the revenue outputs the business treats as authoritative.
Examples might include:
- booked revenue;
- recognized revenue;
- invoiced revenue;
- collections;
- sales pipeline;
- closed-won value;
- active subscriptions;
- renewals;
- average contract value;
- lead-to-opportunity conversion;
- opportunity-to-close conversion.
For each metric, document:
- the business definition;
- the source system or systems;
- the grain;
- the relevant dates;
- the inclusion and exclusion rules;
- currency treatment;
- status logic;
- the owner;
- the expected refresh frequency;
- the report or dashboard where it appears.
This creates a quality contract around business outcomes rather than around abstract database tables.
A test is valuable when failure tells you that a business number may be unreliable.
2. Separate technical health from data health
A mature monitoring design normally needs both.
Technical monitoring covers events such as:
- connector failure;
- API authentication failure;
- orchestration failure;
- warehouse task failure;
- model-build failure;
- dashboard refresh failure;
- gateway outage.
Data-quality monitoring covers different questions:
- Did the expected data arrive?
- Did enough data arrive?
- Did unexpected duplicates appear?
- Did key fields become null?
- Did values move outside plausible ranges?
- Do totals reconcile to the source?
- Did a dimension mapping break?
- Did a business rule stop holding?
Keep these categories visible separately.
If a pipeline runs successfully but source records have stopped arriving, the system should not display green simply because the orchestration job returned success.
3. Monitor freshness at the business-data level
Freshness is one of the most useful revenue-reporting controls.
But freshness should not mean only “the pipeline ran at 6:00 AM.”
Measure the age of the data itself.
For a Salesforce opportunity feed, you might track the latest source modification timestamp observed in the warehouse.
For orders, track the latest order timestamp or ingestion watermark.
For invoices, track the most recent expected accounting activity.
Then define a threshold appropriate to the business.
A daily executive dashboard may tolerate data that is several hours old. An operational sales dashboard may require much shorter latency. A monthly finance dataset may be acceptable on a completely different schedule.
Freshness thresholds should therefore be attached to datasets and business use cases, not applied globally.
A useful alert states what is stale, how stale it is, what report is affected, and who owns the source or pipeline.
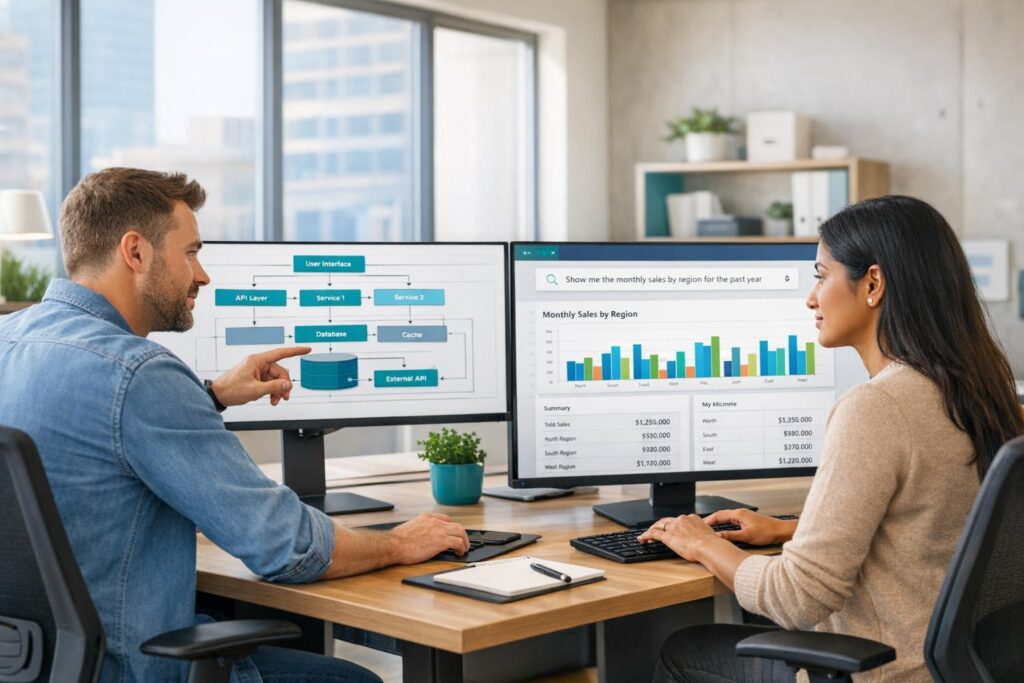
4. Monitor completeness using expected populations
Completeness asks whether all expected records or fields arrived.
The simplest version is row-count monitoring, but raw row counts can be misleading.
A business may naturally process fewer orders on weekends. Sales opportunities may spike at quarter-end. Marketing leads may vary dramatically with campaign activity.
Use context.
Useful completeness controls include:
- source count versus warehouse count;
- records received today versus an expected range;
- count by region, business unit, product or source;
- missing dates in a daily series;
- percentage of required fields populated;
- expected files received;
- expected source partitions loaded.
Segmented monitoring is especially useful.
If total orders are normal but one region suddenly reports zero, an overall row-count test may not detect the issue.
5. Test uniqueness at the business key
Duplicate records can create some of the most damaging revenue-reporting errors because they inflate totals while the dashboard still looks plausible.
Define the key that should be unique for each important entity.
Examples include:
- opportunity ID;
- order ID;
- invoice ID;
- subscription ID;
- customer-system combination;
- transaction ID;
- line-item composite key.
Then monitor duplicate counts.
Be careful with historical models. A slowly changing dimension or snapshot table may legitimately contain multiple rows for the same business entity. In that case, the uniqueness rule must include the effective timestamp, version, snapshot date or other grain-defining field.
The test should reflect the model’s intended grain.
6. Monitor nulls where null actually means something is broken
Testing every column for null values produces noise.
Some fields are legitimately optional. Others become mandatory only after a record reaches a particular state.
Use conditional completeness rules.
For example:
- A closed-won opportunity should have a close date and amount.
- An invoiced order should have an invoice identifier.
- A paid transaction should have a payment date.
- An active subscription should have a customer identifier.
This makes alerts actionable because they represent violated business expectations rather than generic database preferences.
7. Reconcile warehouse totals to operational systems
Reconciliation is one of the strongest controls for executive revenue reporting.
Choose named source reports or source-system queries that represent agreed comparison points.
Then compare material metrics at useful grains.
Do not check only one grand total.
Reconcile by dimensions such as:
- date;
- region;
- business unit;
- currency;
- sales stage;
- product;
- customer type;
- legal entity.
A total can accidentally match while underlying records are wrong. Segmentation makes differences easier to locate.
Actiknow’s guide to a single source of truth makes an important distinction: a reliable analytical environment does not require pretending that one database is the master of every operational fact. Source systems can remain authoritative for operational data while governed analytical definitions create consistent reporting downstream.
That is the right mindset for reconciliation. The warehouse should be able to explain how its numbers relate to the authoritative source.
8. Build record-level exception outputs
An alert saying “revenue mismatch: 2.4%” is useful for detection but weak for resolution.
The monitoring system should help identify the records causing the variance.
Create exception tables or diagnostic outputs that can show:
- source records missing from the warehouse;
- warehouse records missing from the source;
- mismatched amounts;
- mismatched statuses;
- duplicate business keys;
- unmapped dimensions;
- late-arriving records;
- records excluded by a transformation rule;
- currency conversion exceptions.
This dramatically shortens investigation time.
Instead of asking an analyst to manually compare two reports, the system provides a candidate list of differences.
9. Add distribution and anomaly monitoring carefully
Not every quality failure violates a deterministic rule.
Suppose daily revenue is normally between a certain range and suddenly drops 70%. The data may be wrong, or the business may simply have had an unusual day.
Distribution monitoring can detect:
- unusual volume changes;
- sudden shifts in average order value;
- unexpected category mix;
- abnormal null rates;
- dramatic changes in conversion;
- outlier transaction values.
These alerts should be treated differently from hard failures.
A duplicate primary key may be objectively invalid.
A revenue drop may require investigation but could be legitimate.
Label alerts accordingly so teams do not confuse anomaly detection with proof of bad data.
10. Monitor schema changes before they reach dashboards
Operational systems evolve.
A CRM administrator adds a field.
An API changes a data type.
A source renames a status.
A vendor removes a field.
A new enum value appears.
A table gains a column.
Some changes are harmless. Others can break transformations or, worse, change reporting logic without producing a technical failure.
Monitor schema and accepted-value changes for important sources.
For critical fields, maintain expectations around:
- data type;
- presence;
- allowed values;
- relationship behavior;
- semantic meaning.
Schema monitoring should feed a change-management process, not simply create another alert inbox.
11. Validate referential integrity
Revenue reporting often joins multiple business entities.
An order references a customer.
An opportunity references an account.
An invoice references an order.
A line item references a product.
When those relationships fail, records can disappear from reports or fall into “Unknown” categories.
Monitor orphaned relationships.
For example:
- orders with no matching customer;
- opportunities with no account;
- invoice lines with no invoice;
- transactions with no currency mapping;
- sales records with no region mapping.
Not every orphan is necessarily a pipeline defect. Late-arriving dimensions can create temporary exceptions. The monitoring rule should reflect the expected arrival sequence and tolerance.
12. Define thresholds deliberately
Not every test should fail on the first imperfect record.
For some controls, tolerance should be zero.
Duplicate invoice IDs may be unacceptable.
Missing closed-won amounts may be unacceptable.
For others, a threshold may be reasonable.
A small number of late CRM updates may be normal.
A third-party API may occasionally deliver records after the expected window.
Document thresholds with the business owner.
A monitoring system becomes ineffective when engineers choose arbitrary tolerances simply to keep alerts quiet.
13. Give every alert an owner
A data-quality test without ownership is only an observation.
For each critical rule, identify who should act.
Potential owners include:
- data engineering;
- BI team;
- CRM administrator;
- finance operations;
- sales operations;
- source-system vendor;
- business data steward.
Ownership may depend on the failure type.
If Salesforce extraction stops, data engineering may own the incident.
If opportunities are missing required fields, sales operations may own the source-data correction.
If finance and sales disagree about which stage counts toward pipeline, the issue is a business-definition decision rather than an engineering defect.
Route the alert to the team that can actually resolve it.
14. Include business impact in the alert
Not all data incidents deserve the same urgency.
A broken field used only in an exploratory dashboard is different from an error affecting the CEO’s revenue report.
Maintain a simple dependency map between:
- source;
- pipeline;
- model;
- metric;
- dashboard;
- business owner.
Then enrich alerts with impact.
Instead of:
“Test mart_opportunity_17 failed.”
Prefer:
“Closed-won opportunity reconciliation is outside tolerance. Executive Revenue Dashboard and Weekly Sales Review may be affected. Source: Salesforce. Difference: 34 records / ₹X or $X depending on reporting currency. Owner: Sales Operations + Data Engineering.”
The exact format will vary, but business context improves response.
15. Distinguish warning, failure and reporting lockout
A monitoring system should not treat every issue equally.
A useful severity model might include:
- Informational: unusual but not necessarily wrong.
- Warning: quality is degraded but reporting remains usable with caution.
- Critical: a material metric is likely unreliable.
- Blocked: the dataset should not be published or certified until resolved.
For highly sensitive financial reporting, it may be appropriate to prevent publication when critical reconciliation controls fail.
For operational dashboards, displaying a freshness warning may be more useful than making the entire report unavailable.
Decide this behavior with the business.
16. Track data-quality incidents over time
Monitoring should generate management information about the data platform itself.
Track:
- number of incidents;
- time to detection;
- time to resolution;
- repeat failures;
- failures by source;
- failures by owner;
- most common rule types;
- percentage of critical datasets covered by monitoring.
This helps leadership distinguish between occasional source anomalies and structural reliability problems.
It also identifies where engineering effort should be invested.
If the same manual spreadsheet causes failures every month, the answer may be to redesign the process rather than add another alert.
17. Avoid the trap of thousands of low-value tests
Modern data tools make it easy to create tests.
That does not mean every possible test should exist.
A test has operational cost:
- someone must understand it;
- alerts must be routed;
- false positives must be investigated;
- thresholds must be maintained;
- business changes must be reflected.
Prioritize controls using business impact and likelihood.
Start with the small set of revenue metrics executives rely on, then expand coverage across their upstream dependencies.
Quality monitoring should increase trust, not create alert fatigue.
A practical monitoring architecture
A revenue data-quality system can be designed in layers.
Layer 1: Source availability
Can the required source be reached, and did expected source activity occur?
Layer 2: Ingestion
Did the expected records, files or API windows arrive?
Layer 3: Structural quality
Are schema, types, keys, null behavior and relationships valid?
Layer 4: Transformation quality
Did business rules, mappings and joins behave as expected?
Layer 5: Reconciliation
Do material warehouse metrics reconcile to agreed source outputs?
Layer 6: Distribution monitoring
Are important values or volumes behaving unusually?
Layer 7: Reporting readiness
Are freshness and critical quality checks good enough to certify or publish the dataset?
Layer 8: Incident workflow
Who is notified, what is affected, and how is resolution tracked?
This layered design makes failures easier to diagnose because teams can see where trust was lost.
A practical first set of revenue quality controls
If an organization is starting from zero, begin with a manageable set.
For each critical revenue dataset, implement:
- freshness of source data;
- source-to-warehouse record-count comparison;
- duplicate business-key check;
- conditional null checks on material fields;
- referential-integrity checks;
- reconciliation of the primary financial or sales measure;
- reconciliation by at least one useful business dimension;
- alert routing;
- incident ownership;
- a visible data-quality status for report owners.
Then add anomaly and distribution controls once the deterministic checks are stable.
Where should the monitoring logic live?
There is no single required architecture.
Controls may run in ingestion tooling, orchestration, SQL, transformation frameworks, warehouse tasks, observability platforms or BI processes.
The important design principle is that the test should run close enough to the relevant layer to diagnose the problem while results are centralized enough to provide a coherent quality view.
Do not force every test into the same technology merely for consistency.
What executives should ask about revenue data quality
Leadership does not need to review individual SQL tests.
It should be possible to answer:
- Which revenue metrics are actively monitored?
- How fresh is the data?
- Which source systems are reconciled?
- What happens when reconciliation fails?
- Who owns each critical incident?
- How quickly are failures detected?
- Can we identify the records causing a mismatch?
- Do dashboards indicate when data is stale or uncertified?
- Which recurring quality problems remain unresolved?
Those questions reveal whether data quality is an engineering practice or simply an assumption.
Frequently asked questions
What is data quality monitoring?
Data quality monitoring continuously checks whether data meets defined expectations for areas such as freshness, completeness, uniqueness, validity, relationships and reconciliation. It differs from pipeline monitoring, which primarily checks whether technical processes completed.
What data quality checks are most important for revenue reporting?
Start with freshness, source-to-warehouse completeness, duplicate business keys, required-field rules, relationship integrity and reconciliation of material revenue metrics. The exact rules should follow the business definition.
How often should data quality tests run?
Tests should align with the data’s refresh and decision cycle. A near-real-time operational feed may require frequent checks. A daily executive dataset may only need controls after each scheduled load.
Should a dashboard be blocked when a data quality test fails?
Only for failures serious enough to make the report materially unreliable. Some incidents justify blocking publication, while others are better handled with warnings. Define severity and reporting behavior in advance.
How do you avoid false data-quality alerts?
Use business-aware thresholds, segment expected patterns appropriately, distinguish hard rules from anomaly warnings, and review recurring false positives. Tests that nobody trusts should be redesigned or removed.
Who owns data quality?
Ownership is shared. Data engineering can own pipeline and transformation reliability, while business teams own source-data processes and metric definitions. Each individual control should still have a named operational owner.
Do we need a dedicated data observability platform?
Not necessarily. Organizations can begin with SQL tests, orchestration checks, warehouse monitoring and structured alerting. Dedicated observability tooling becomes more valuable as the number of sources, datasets, dependencies and teams grows.
Trust should be measurable
Executives should not have to ask an analyst whether a revenue dashboard “looks right.”
A well-designed reporting platform can provide evidence: the data arrived on time, expected records are present, key relationships hold, material totals reconcile, exceptions are visible, and somebody is accountable when a control fails.
That is the purpose of data quality monitoring.
If your organization is building or improving revenue reporting, Actiknow can help design the data integration, warehouse, BI and monitoring layers needed to make reporting more dependable. Contact Actiknow to discuss the reporting architecture and the controls that should sit around it.