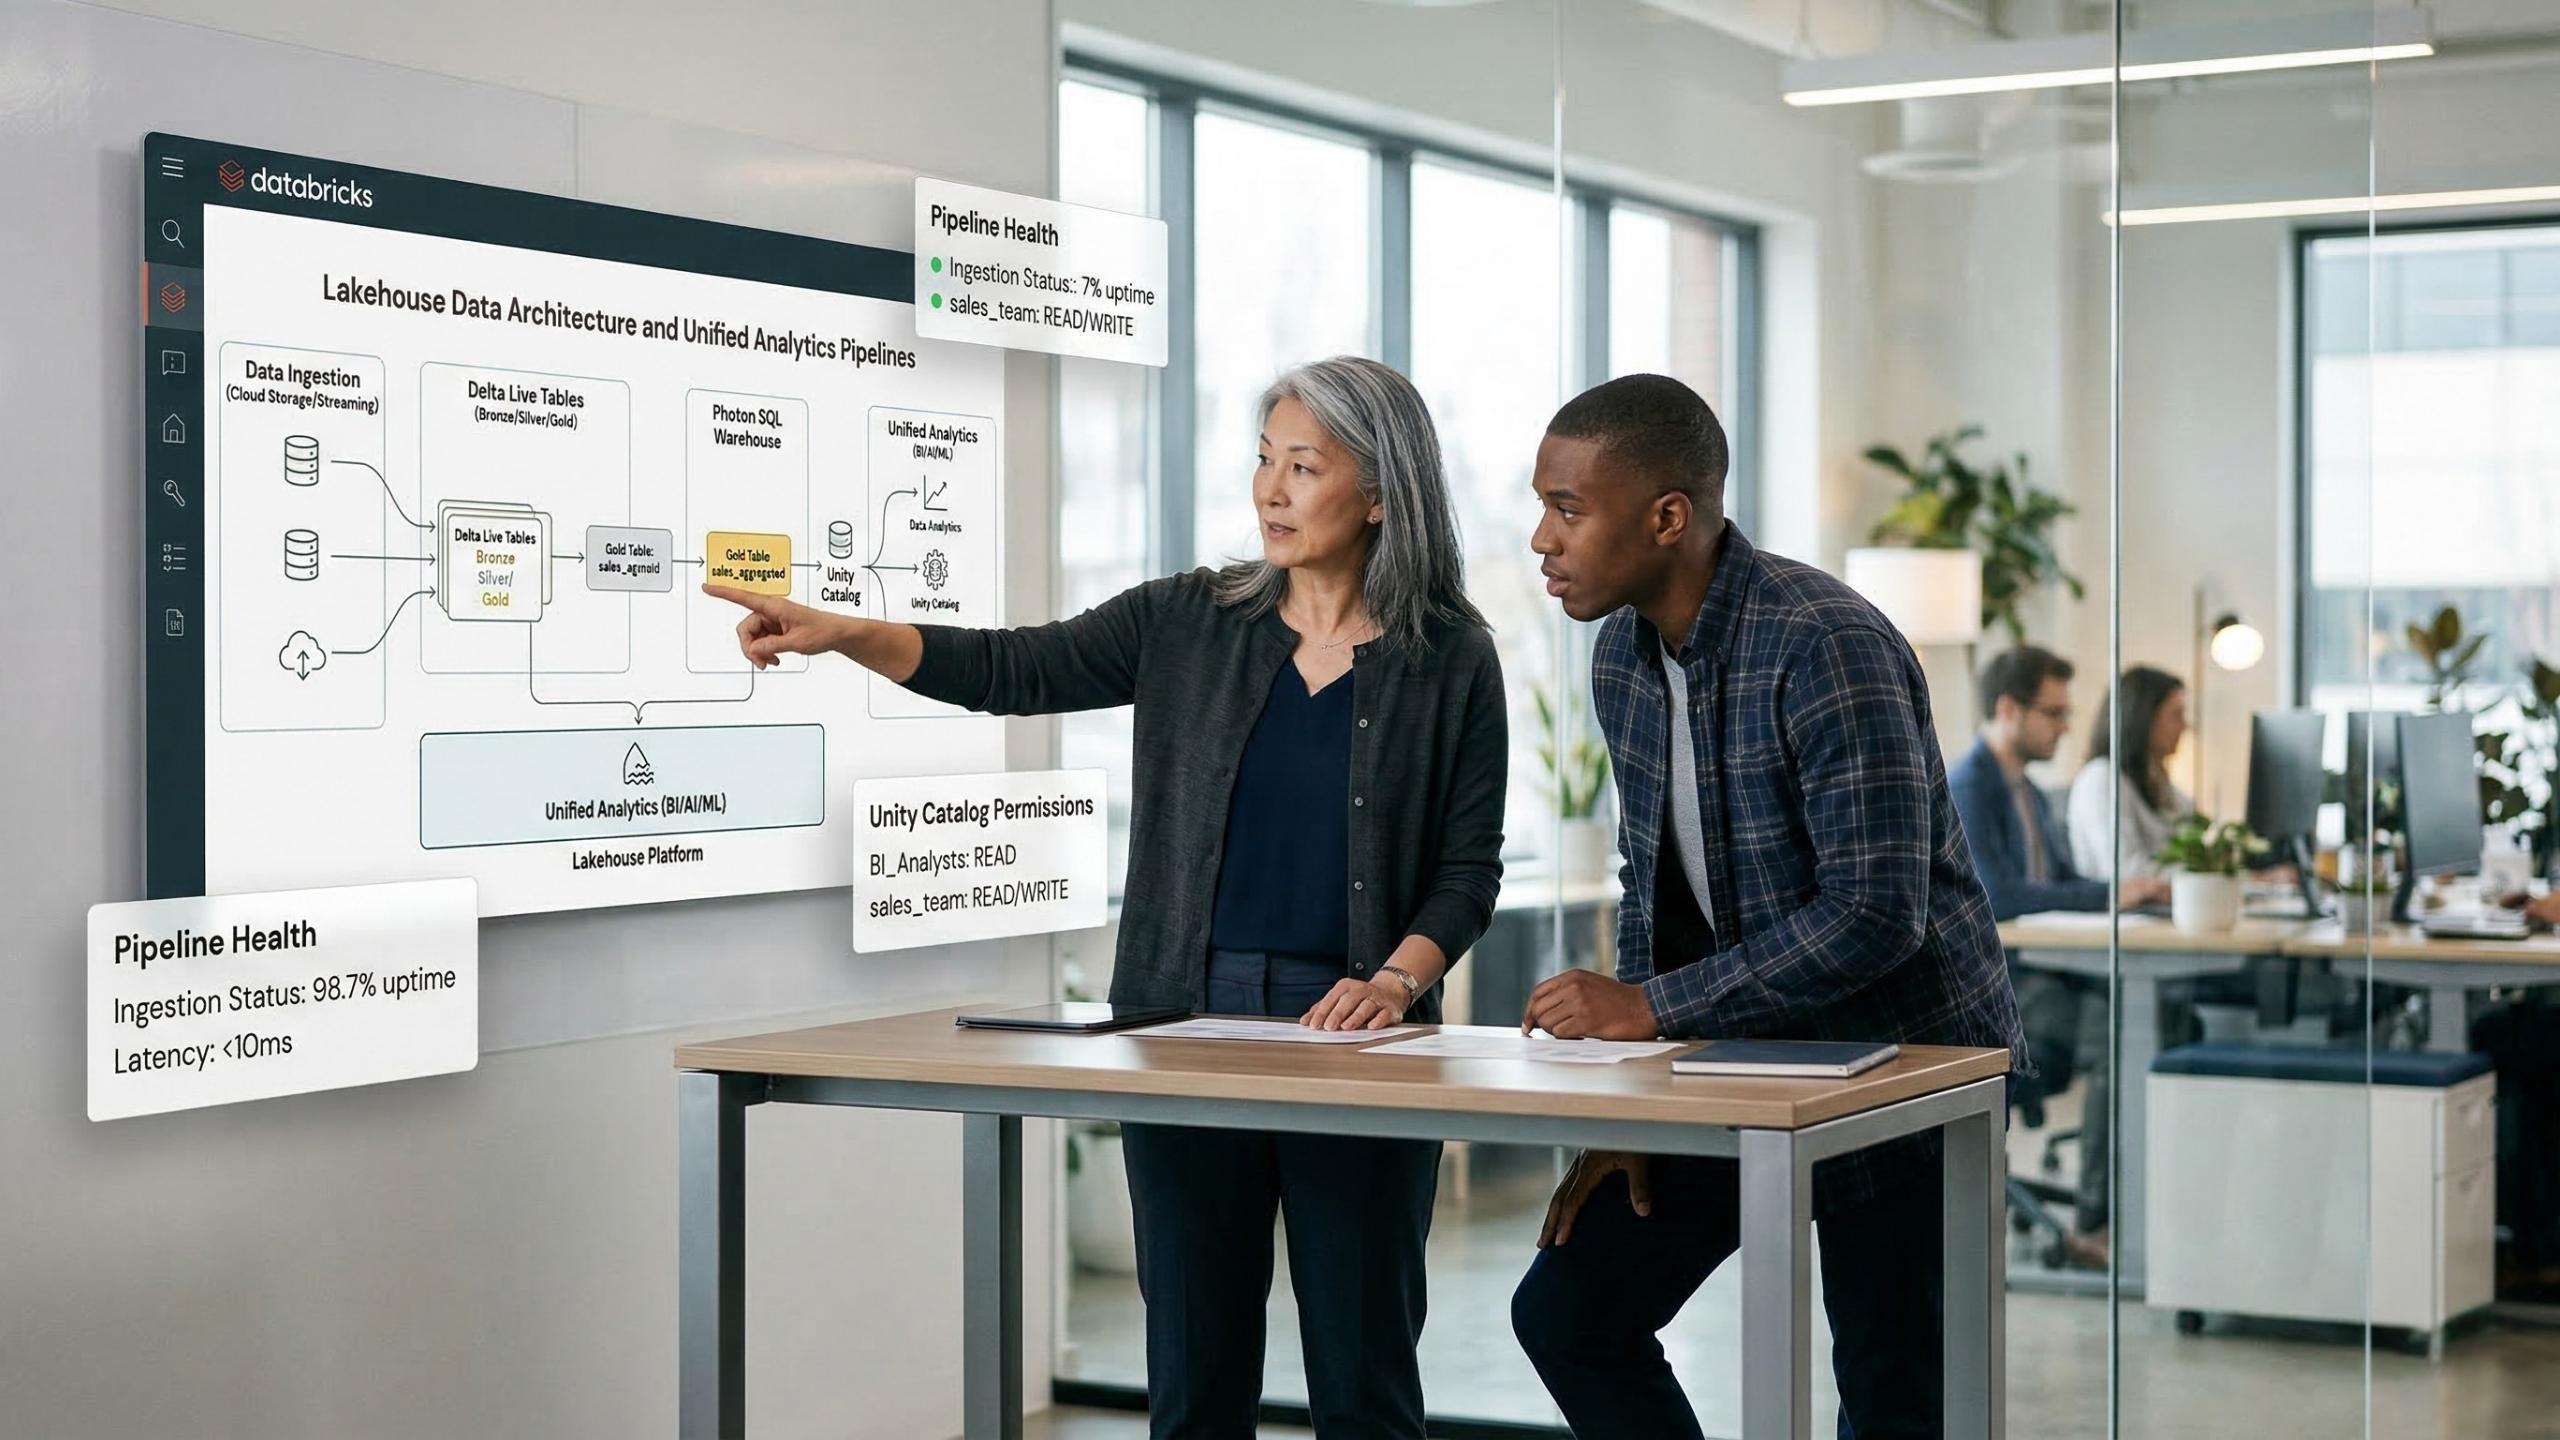
For years, ETL was the default pattern for moving business data into an analytical system. Data was extracted from operational applications, transformed into the required structure, and then loaded into a warehouse. The rise of scalable cloud data platforms made another pattern increasingly practical: ELT, where data is extracted, loaded first, and transformed inside the destination platform.
The difference sounds like a minor change in sequence. It is not. ETL versus ELT affects where computing happens, how quickly new data can be made available, how much raw history you retain, how governance is implemented, what skills your team needs, and where costs accumulate.
For executives, the useful question is therefore not “Which acronym is better?” It is: “Which operating model gives us reliable, governed data at the speed and cost our business actually needs?”
Actiknow’s Business Intelligence services include integrating data from databases and APIs, creating solution architectures, data modeling, dashboards, automation, publishing, and refresh mechanisms. These are the kinds of downstream requirements that should shape an integration architecture rather than being treated as an afterthought.
What Is ETL?
ETL stands for Extract, Transform, Load.
- Extract data from source systems such as CRM, ERP, finance platforms, databases, files, or APIs.
- Transform it before it reaches the analytical destination. This can include cleaning, standardizing, joining, filtering, masking, validating, and applying business rules.
- Load the prepared data into the warehouse or reporting store.
Traditional ETL became popular when analytical databases were comparatively expensive and constrained. It often made sense to do transformation elsewhere and load only the curated data required for analysis.
ETL can still be the right architecture. For example, an organization may need sensitive fields removed or tokenized before data enters a particular environment. A destination may have limited transformation capability. Or a highly controlled pipeline may deliberately accept only validated records.
What Is ELT?
ELT stands for Extract, Load, Transform.
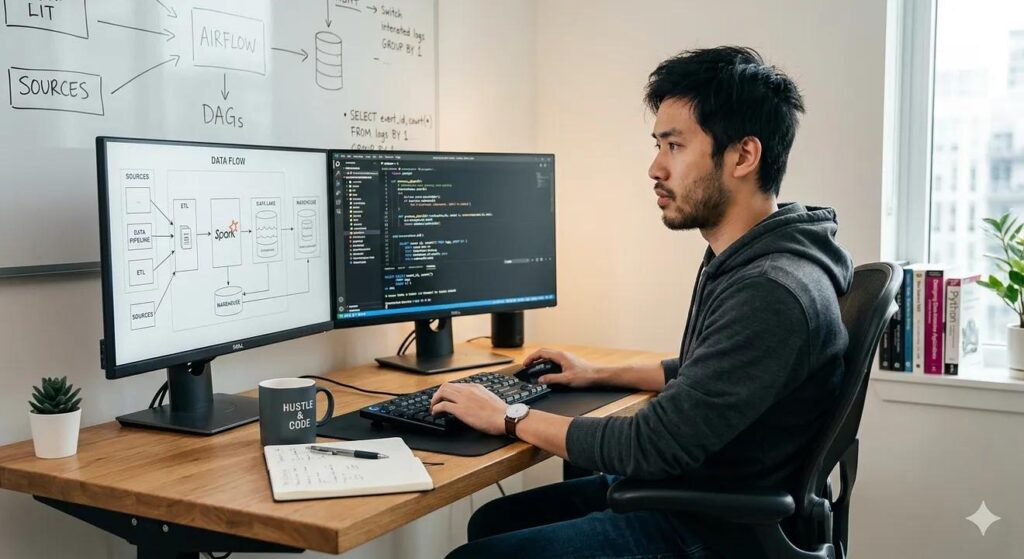
The source data is first copied into the target data platform, often in a relatively raw form. Transformations then run inside that platform to create cleaned, standardized, modeled, and business-ready datasets.
Modern cloud warehouses made this pattern attractive because they provide substantial storage and compute capacity and can execute transformation workloads close to the data. Teams can preserve source-level history while building multiple downstream models for finance, sales, operations, marketing, and other uses.
The important distinction is not that ELT eliminates transformation. It changes where and when transformation happens.
ETL vs ELT: The Executive Comparison
1. Speed to ingest new data
ELT can reduce the work required before initial ingestion. A new source can often be landed first and modeled afterward. This is useful when teams want to preserve source data quickly or when downstream requirements are still evolving.
ETL places more logic before loading. That can slow onboarding, but the destination receives data that has already passed defined transformation rules.
Executive question: Is the priority to make source data available quickly, or to ensure only approved structures enter the destination?
2. Flexibility when business definitions change
Suppose Finance changes the definition of active customer, Sales needs a different account hierarchy, or Marketing changes channel grouping. If sufficiently detailed source data has been retained, an ELT architecture can often rebuild downstream models without re-extracting historical data.
With ETL, flexibility depends heavily on what was retained. If transformation discarded fields or granularity before loading, reconstructing history may require another extraction from the source, assuming the source still holds it.
Executive question: How often do reporting definitions change, and do we need the ability to reproduce history under new rules?
3. Governance and sensitive data
A common misconception is that ETL is governed and ELT is not. Either approach can be well governed or poorly governed.
The real question is where controls are applied. ETL can remove or mask sensitive data before it reaches the warehouse. ELT can retain raw data while applying tightly controlled access to raw layers and exposing curated datasets to most users.
If regulations, contractual obligations, or internal policies prohibit certain data from entering an environment at all, pre-load transformation may be necessary. If raw retention is acceptable, governance can be enforced through access controls, curated layers, masking, lineage, testing, and audit processes.
4. Compute and cost
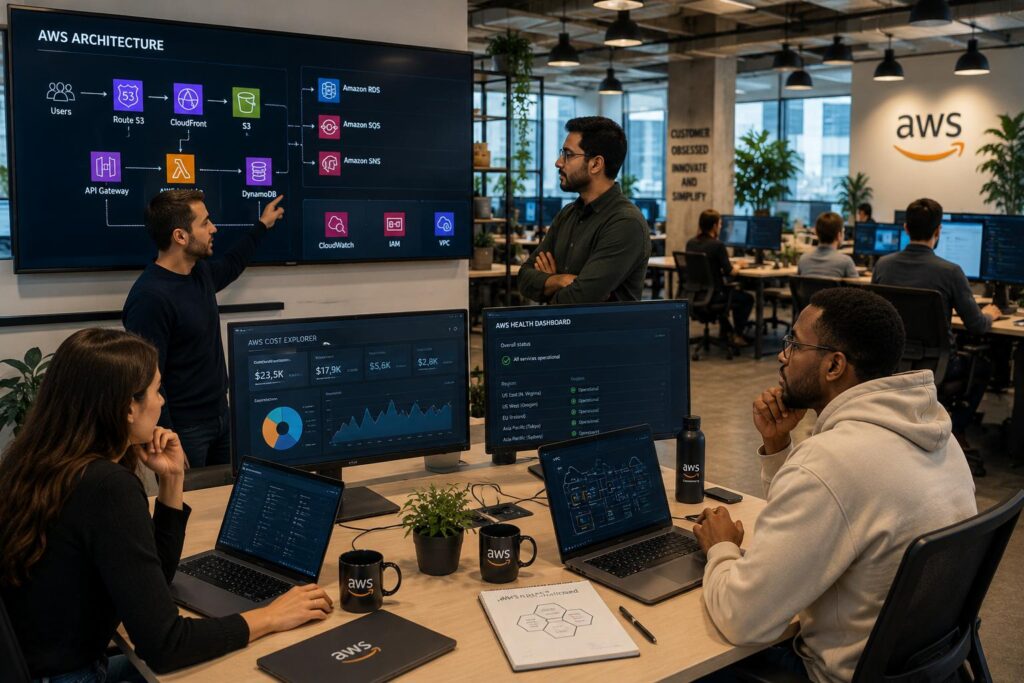
ELT moves transformation compute into the warehouse. That simplifies architecture in some environments but does not make processing free. Poorly designed transformations, unnecessary full rebuilds, excessive refresh frequency, and uncontrolled user workloads can all increase cloud costs.
ETL may shift some compute to external integration infrastructure. It can also reduce the amount of data stored or processed downstream, but introduces another processing layer that must be operated and monitored.
Compare total cost, not merely warehouse storage or connector licensing. Include ingestion, transformation compute, orchestration, monitoring, engineering effort, failed-job recovery, data retention, and support.
5. Raw-data retention and auditability
Keeping an immutable or near-source copy of incoming data can be extremely valuable. It gives engineering teams a reference point when business users question a number, transformation logic changes, or a source-system issue is discovered later.
ELT naturally encourages this layered pattern: raw data, standardized data, and business-ready models. ETL can retain raw data too, but only if the architecture deliberately includes that layer.
6. Data quality
Neither ETL nor ELT automatically produces trustworthy data. Data quality depends on explicit tests and reconciliation.
At minimum, production pipelines should consider freshness, completeness, duplicate records, nulls in critical fields, schema changes, referential integrity, expected ranges, source-to-destination counts, and reconciliation of important financial or operational totals.
A pipeline that completes successfully can still deliver incorrect business data.
7. Skills and operating model
ELT often aligns well with teams using SQL-centric transformation workflows because substantial modeling occurs in the analytical platform. ETL may require deeper expertise in integration tooling or transformation engines outside the warehouse.
Architecture should reflect the team that will maintain it after launch. A technically elegant design that only one specialist understands is an operational risk.
When ETL Is Usually the Better Fit
ETL deserves serious consideration when data must be transformed, filtered, anonymized, or validated before entering the target environment; the destination has limited transformation capacity; source data is extremely large but only a small curated subset has analytical value; regulatory or contractual boundaries constrain raw-data movement; or an existing ETL estate is stable, economical, and well governed.
Do not replace a functioning ETL architecture merely because ELT is newer. Migration needs a measurable business reason.
When ELT Is Usually the Better Fit
ELT is often attractive when the organization uses a scalable cloud analytical platform; analysts and data engineers need detailed historical data; business definitions change frequently; several teams need different models from the same source data; rapid onboarding of new sources matters; SQL-based transformation is a strong internal capability; or preserving source-level data improves auditability and reprocessing.
Actiknow’s Custom Solutions capabilities include API integrations, database and data lake setup, and automation, illustrating why integration decisions often sit within a broader architecture rather than a single pipeline tool.
The Hybrid Model Is Often the Practical Answer
Real enterprise architectures rarely fit neatly into one acronym. A company may perform lightweight pre-load processing for security and technical compatibility, load detailed data into a warehouse, and then perform most business transformations there.
For example:
- Extract customer, transaction, and product data.
- Remove fields that are prohibited from the analytical environment.
- Load permitted source-level data into controlled raw schemas.
- Standardize identifiers and data types inside the warehouse.
- Build conformed customer, product, and calendar dimensions.
- Apply business definitions in curated models.
- Publish certified datasets for Power BI, Tableau, Looker Studio, or other consumers.
That is technically a hybrid approach, and the label matters far less than whether the responsibilities are explicit.
A Practical Decision Framework
Before choosing ETL or ELT, answer seven questions.
First, what data is legally and contractually allowed in the destination? This can eliminate options immediately.
Second, how much source-level history must be retained? Consider future reprocessing, audits, changing definitions, and debugging.
Third, where is transformation most economical and manageable? Compare warehouse compute with external processing, including engineering overhead.
Fourth, how quickly must a new source become usable? Distinguish ingestion speed from the time required to produce trusted business metrics.
Fifth, who owns transformation logic? Decide whether it belongs primarily with integration engineers, analytics engineers, application teams, or a shared data function.
Sixth, how will correctness be proven? Define reconciliation tests before building dashboards.
Seventh, how will failures be detected and recovered? Monitoring, retries, alerting, backfills, and ownership are architectural requirements, not post-launch enhancements.
A Sensible Layered Architecture
For many modern analytical environments, a useful pattern is:
Source layer: Operational applications remain systems of record.
Ingestion layer: Connectors, APIs, files, database replication, or custom pipelines move data reliably.
Raw layer: Source-aligned data is retained with restricted access where appropriate.
Standardized layer: Types, keys, naming, deduplication, and common entities are normalized.
Business layer: Governed metrics and business rules are applied.
Consumption layer: Dashboards, applications, exports, APIs, data science, and AI consume approved datasets.
This separation makes responsibilities visible. It also reduces the temptation to bury important business logic inside individual dashboards.
What to Measure After Implementation
Architecture decisions should eventually be judged operationally. Useful measures include pipeline success rate, data freshness against SLA, reconciliation exceptions, mean time to recovery, cost per pipeline or workload, number of manual interventions, time required to onboard a new source, time required to implement a definition change, and percentage of executive metrics backed by governed models.
These measures are more meaningful than declaring an ETL or ELT migration successful simply because data arrived.
Common Mistakes to Avoid
Choosing based on fashion. Cloud-native does not automatically mean ELT is appropriate for every dataset.
Transforming without retaining evidence. If important records are discarded before you can reconcile them, debugging becomes unnecessarily difficult.
Loading everything without access discipline. Raw retention is useful only when permissions, retention, and sensitive-data rules are deliberate.
Treating the warehouse as infinite compute. ELT can make experimentation easy, but unmanaged transformation workloads can become expensive.
Putting business rules in too many places. Revenue, customer status, region, and other shared definitions should not be independently recreated in every dashboard.
Ignoring recovery. The architecture is incomplete until the team knows what happens after a partial load, API outage, schema change, duplicate delivery, or failed transformation.
The Bottom Line
ETL and ELT are not competing ideologies. They are architectural patterns with different tradeoffs.
ETL gives organizations more control before data enters the analytical destination. ELT takes advantage of modern analytical platforms to retain detailed data and move transformation closer to the warehouse. A hybrid model can combine pre-load controls with flexible in-platform modeling.
For most executives, the decision should be based on five things: data sensitivity, required flexibility, platform capabilities, total operating cost, and the team that will own the system.
The best architecture is the one that makes trusted data repeatable. It should let the business trace important numbers to their sources, change definitions without unnecessary reconstruction, recover from failures, control access, and operate at a cost the organization understands.
FAQs
What is the main difference between ETL and ELT?
ETL transforms data before loading it into the destination. ELT loads data first and performs most transformations inside the target analytical platform.
Is ELT always better for cloud data warehouses?
No. Cloud warehouses make ELT practical, but security requirements, source volumes, destination constraints, team skills, and economics can still favor ETL or a hybrid design.
Does ELT mean raw data is available to everyone?
It should not. Raw data can be retained in restricted schemas or layers while most users access governed, curated datasets.
Is ETL more secure than ELT?
Not inherently. ETL can prevent sensitive data from reaching a destination, which is important in some environments. ELT can also be secure when raw data is permitted and protected with appropriate access, masking, retention, and auditing controls.
Can a company use ETL and ELT together?
Yes. Many practical architectures use pre-load transformations for security or compatibility and perform business modeling after loading.
Does changing from ETL to ELT reduce costs?
Not automatically. It can simplify some pipeline components, but warehouse compute, storage, orchestration, monitoring, engineering, and support still have costs. Compare the full operating model.
How should we choose between ETL and ELT for a new data platform?
Start with data restrictions, latency requirements, raw-history needs, transformation complexity, platform capability, team skills, reconciliation requirements, and total cost. Choose the pattern after those constraints are understood.
Call to Action
If you are designing or modernizing a data integration and reporting architecture, Actiknow can help assess the sources, transformation requirements, data model, integrations, dashboards, refresh mechanisms, and operating controls as one system. Explore Actiknow’s Business Intelligence capabilities or contact Actiknow to discuss the architecture you are considering.