dbt is not primarily a dashboard tool or a data-movement tool
For business leaders, dbt can be confusing because it sits in the middle of the data stack.
It does not usually extract Salesforce, ERP or advertising data into the warehouse. It does not replace Snowflake, BigQuery or Redshift. It is not the dashboard where executives view KPIs.
Instead, dbt helps teams turn raw warehouse data into tested, documented and reusable analytical data models.
That middle layer matters more as a company’s reporting estate grows.
Without a disciplined transformation process, business logic tends to spread across SQL scripts, dashboard calculations, analyst notebooks, spreadsheets and one-off queries. Revenue may be calculated differently in finance and sales. “Active customer” may mean one thing in an executive dashboard and another in a product report. A change to source data may silently break downstream metrics.
Analytics engineering addresses this problem by applying software-engineering practices to analytical transformations.
Actiknow’s data engineering services cover data integration, ETL and ELT, warehouse architecture, migration and ongoing data operations. dbt typically fits into that environment after data has landed in the warehouse and before governed datasets are consumed by BI tools.
What does dbt actually do?
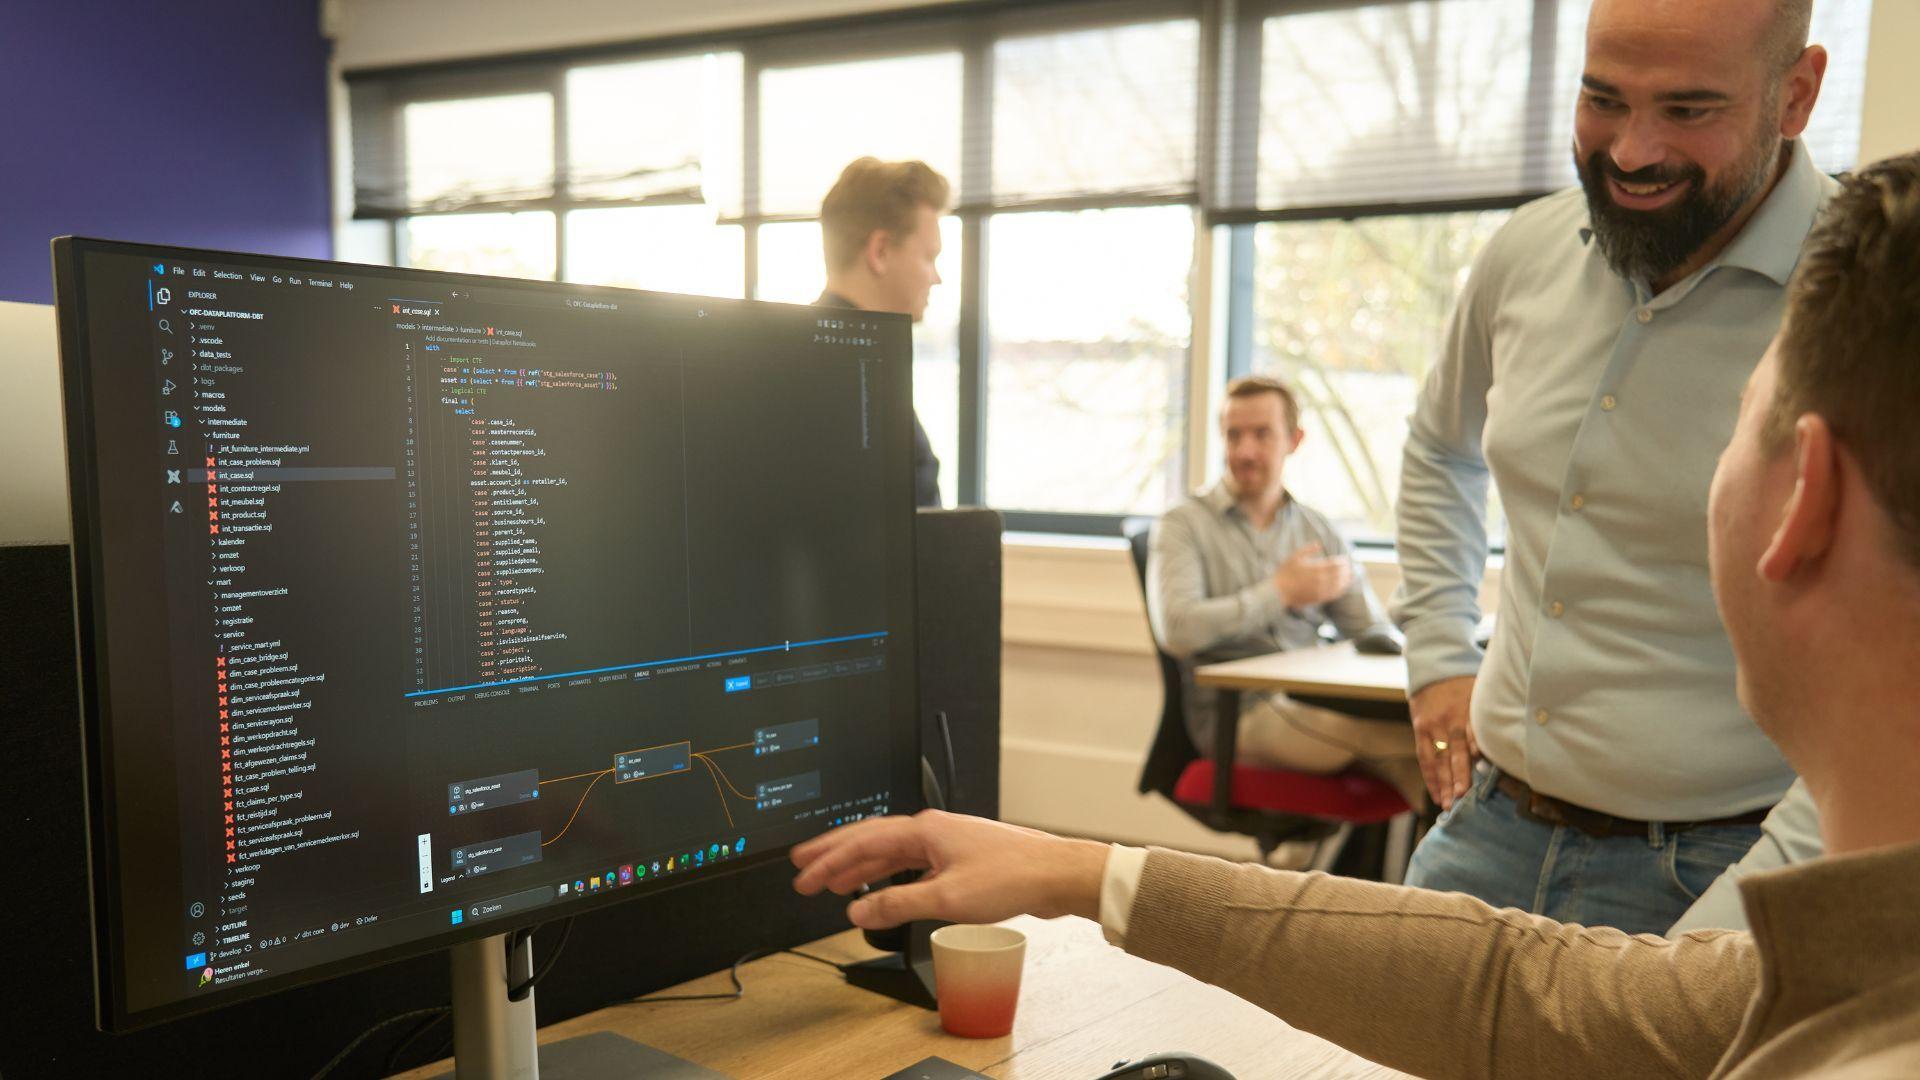
At its core, dbt lets teams define transformations as code.
A raw warehouse may contain tables such as:
raw_salesforce.opportunity;
raw_salesforce.account;
raw_erp.invoice;
raw_product.subscription.
Those tables reflect operational source systems. They are not necessarily ready for executive reporting.
An analytics engineering layer can transform them into models such as:
stg_opportunity;
stg_invoice;
dim_customer;
fct_revenue;
mart_sales_pipeline;
mart_executive_revenue.
Each model has a defined purpose and dependencies.
dbt compiles and runs the transformation logic in the warehouse itself. It also provides mechanisms for testing, documentation, lineage, version control integration and deployment workflows.
The business value is not the SQL syntax. It is the operating discipline around analytical logic.
1. Move recurring business logic out of dashboards
One of the most important reasons to introduce analytics engineering is to reduce repeated logic.
Imagine five dashboards that all need “net revenue.”
If each report calculates it independently, the organization effectively has five implementations of the metric.
Even if all five start identically, they can diverge.
One analyst changes refund treatment.
Another excludes internal customers.
A third uses invoice date rather than recognition date.
Soon, meetings become arguments about which number is correct.
A better architecture places stable business rules in a governed analytical model and lets dashboards consume the result.
Not every calculation belongs upstream. Visual-specific ratios or interactive calculations may still live in BI. But reusable business definitions should have an intentional home.
2. Make transformations reviewable
In many organizations, a critical reporting transformation begins as a SQL query written by one analyst.
The query works, so it gets scheduled.
Months later, nobody is certain why a filter exists.
Analytics engineering treats that transformation more like application code.
Changes can be stored in version control.
A proposed change can be reviewed before it reaches production.
Reviewers can see exactly what logic changed.
The team can associate changes with tickets or business requests.
Previous versions remain available.
This improves accountability for metrics that influence important decisions.
It also reduces dependence on one person remembering why the query works.
3. Test the data model automatically
Traditional BI testing often happens at the end.
An analyst refreshes a dashboard, compares some totals and checks whether charts look reasonable.
That is necessary, but it is not enough.
dbt allows tests to be attached directly to analytical models.
Examples include:
- customer IDs should be unique;
- invoice IDs should not be null;
- every opportunity account should map to a valid account;
- accepted status values should stay within a defined set;
- a critical business condition should always hold.
Teams can also write custom tests for business-specific rules.
Testing does not prove that every number is correct, but it catches structural problems earlier in the pipeline.
This is particularly valuable when source systems change.
If a CRM starts sending an unexpected status or a join suddenly creates duplicates, a model test can fail before the issue reaches executive reporting.
4. Build lineage into the transformation layer
Executives often see a KPI at the end of a long chain.
Dashboard → semantic model → reporting mart → transformed table → staging model → raw source.
When the number is questioned, the team needs to trace that chain.
dbt can generate model lineage based on declared dependencies.
This helps engineers and analysts understand:
- what feeds a model;
- what depends on it;
- which downstream assets may be affected by a change.
Lineage is useful for impact analysis.
If a team changes the definition of customer status, it can identify which models depend on that logic before deploying the change.
Lineage does not replace business documentation, but it provides an important technical map.
5. Separate raw, staging and business-ready data
A warehouse becomes difficult to manage when raw source tables sit beside final reporting tables without clear conventions.
A common analytics engineering structure uses layers.
- Raw layer: Data arrives from source systems with minimal modification.
- Staging layer: Fields are renamed, typed, standardized and lightly cleaned.
- Intermediate layer: Reusable transformations combine or reshape data.
- Mart layer: Business-ready datasets support domains such as sales, finance, marketing or membership.
The exact naming is less important than the separation of responsibilities.
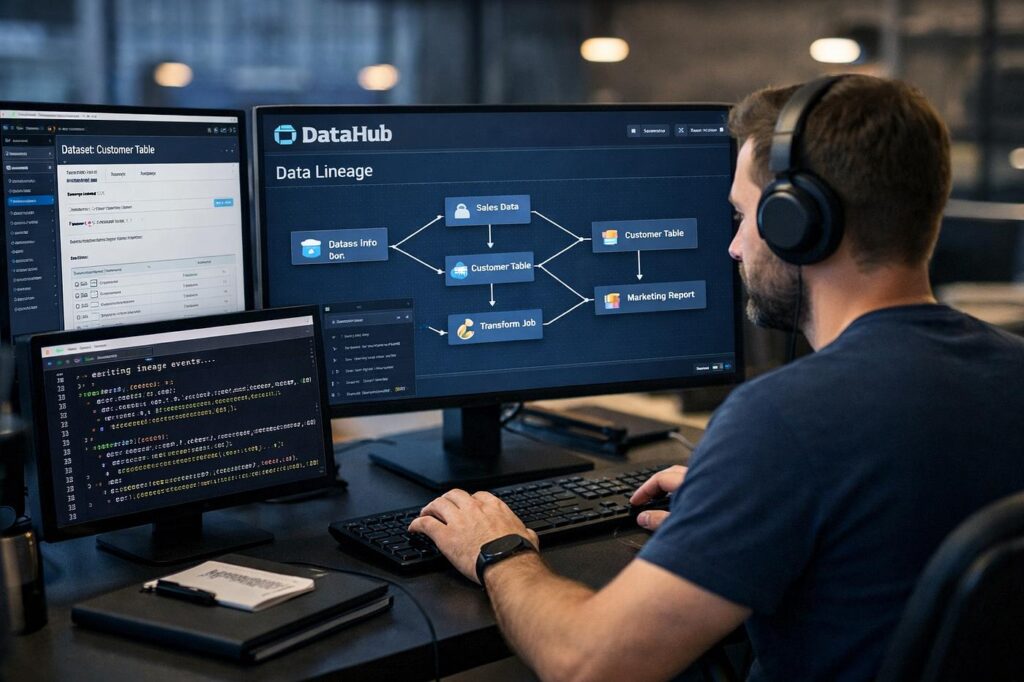
This structure helps teams distinguish source truth from analytical interpretation.
Actiknow’s guide to creating a single source of truth describes the need for governed definitions, validation and ownership across the analytical stack. A structured transformation layer is one mechanism for implementing that discipline.
6. Treat metric definitions as governed assets
A data warehouse is not automatically a single source of truth.
It can contain several conflicting definitions of the same KPI.
The challenge is semantic, not merely physical.
For each important metric, organizations should define:
- business meaning;
- owner;
- source fields;
- calculation;
- grain;
- date logic;
- inclusions and exclusions;
- currency treatment where relevant;
- effective date of definition changes.
dbt can encode much of the transformation logic, while governance processes establish who has authority to change the definition.
This distinction matters.
Technology can make a metric consistent once the business has agreed what the metric means. Technology cannot resolve an unresolved business disagreement by itself.
7. Use environments instead of editing production logic directly
As analytical systems mature, changing production SQL manually becomes risky.
A disciplined workflow separates development and production.
An analytics engineer creates a branch.
The change runs against a development environment.
Tests execute.
A reviewer examines the code.
Automated checks run.
The approved change is merged.
A deployment process updates production.
This resembles modern software delivery because analytical logic increasingly behaves like software.
A revenue model can be as business-critical as an application feature. It deserves controlled deployment.
8. Add documentation where users need context
Technical model names are not sufficient documentation.
A useful analytics engineering practice documents:
- what the model represents;
- its grain;
- important columns;
- source dependencies;
- known assumptions;
- business owners;
- tests;
- refresh behavior.
Documentation helps analysts discover the right dataset rather than creating another version.
It also makes onboarding easier.
A new analyst should not need to reverse-engineer hundreds of SQL queries to learn how revenue reporting works.
9. Improve incremental processing
Large warehouse transformations do not always need to rebuild every row.
Incremental models can process only new or changed data.
This can reduce compute and shorten transformation times.
However, incremental processing introduces design decisions:
- What identifies new records?
- Can old records change?
- How are late-arriving updates handled?
- What happens when transformation logic changes?
- When is a full rebuild required?
- How are deletes treated?
Analytics engineering makes these choices explicit and repeatable.
The objective is not simply faster SQL. It is a transformation process the team can operate reliably.
10. Make warehouse changes safer
Suppose an upstream source field changes.
Without lineage and tests, the effect may only become visible when an executive notices a strange dashboard.
With a governed transformation workflow, the team has more opportunities to detect the problem:
- source freshness checks;
- schema checks;
- staging model tests;
- relationship tests;
- business-rule tests;
- reconciliation;
- deployment checks.
dbt is one part of this control environment.
It should complement source monitoring, ingestion monitoring and BI validation rather than replace them.
11. Understand what dbt does not solve
dbt is valuable, but it should not be treated as a universal data platform.
It does not automatically solve:
- source extraction;
- real-time streaming;
- master data management;
- metric governance disagreements;
- warehouse security;
- BI permissions;
- source-data quality;
- business ownership;
- dashboard design;
- incident management.
It can contribute to some of these areas through tests, models and documentation, but the surrounding operating model still matters.
This is important for executives evaluating tooling.
Buying dbt does not create analytics engineering. A team must adopt the practices.
12. Define ownership of the transformation layer
Who should own dbt models?
The answer depends on the organization.
A centralized data team may own core warehouse models.
Domain analysts may own business-specific marts.
Analytics engineers may sit between data engineering and BI.
A federated model may allow departments to contribute within shared standards.
Whatever model is chosen, define:
- who can create production models;
- who reviews changes;
- who owns shared dimensions;
- who owns critical metrics;
- who responds to failed tests;
- who approves breaking changes;
- who maintains documentation.
Without ownership, the repository can become another collection of unmanaged SQL.
13. Establish naming and modeling standards
Consistency reduces cognitive load.
Useful standards might cover:
- source definitions;
- staging prefixes;
- fact and dimension naming;
- model grain;
- primary keys;
- date fields;
- audit columns;
- materialization choices;
- folder structure;
- test requirements;
- documentation requirements.
The exact conventions are less important than applying them consistently.
A warehouse that has grown for years without standards may benefit from introducing them gradually rather than attempting a disruptive rewrite.
14. Connect dbt to CI/CD
One of the strongest analytics engineering practices is automated validation before changes reach production.
A continuous integration process can:
- build modified models;
- run relevant tests;
- check SQL;
- validate dependencies;
- compare results;
- prevent deployment when required controls fail.
This reduces the risk that one transformation change breaks unrelated reporting.
The more business-critical the warehouse becomes, the more valuable these controls are.
15. Use tests according to business impact
More tests are not automatically better.
A model with hundreds of noisy tests can be less useful than one with ten meaningful controls.
Prioritize:
- primary-key uniqueness;
- required fields;
- relationships;
- accepted values;
- material business rules;
- reconciliation;
- freshness where appropriate.
A test should have an owner and an expected response.
If nobody acts when it fails, question why it exists.
16. Reconcile critical models to source systems
Automated structural tests are not enough for important financial or revenue reporting.
A perfectly unique, non-null dataset can still calculate revenue incorrectly.
For critical marts, compare warehouse outputs to agreed source totals.
Reconcile at useful grains such as:
- date;
- region;
- business unit;
- product;
- currency;
- status.
Actiknow’s data quality monitoring guidance emphasizes freshness, completeness, uniqueness, relationships and reconciliation as complementary controls. Analytics engineering is strongest when model tests sit inside that broader quality framework.
17. Plan for historical logic changes
Business definitions change.
A company may redefine an active customer.
Sales stages may change.
Revenue recognition rules may evolve.
Regions may be reorganized.
When logic changes, decide whether it applies:
- only going forward;
- to all historical data;
- from a specific effective date.
This decision should be documented.
Otherwise, rebuilding a model can unexpectedly rewrite history.
Analytics engineering provides the technical workflow for implementing the change, but business owners must decide the intended historical behavior.
18. Think about deployment frequency
Not every transformation needs the same schedule.
Staging models may run after every ingestion.
Operational marts may refresh frequently.
Executive reporting may refresh hourly.
Finance models may follow controlled daily or close-period processes.
Separate model dependency from business refresh requirement.
A faster warehouse is not automatically a better warehouse if users do not need the additional freshness.
19. Measure analytics engineering outcomes
Leadership should not evaluate analytics engineering by counting dbt models.
Measure improvements such as:
- fewer conflicting KPI definitions;
- faster investigation of reporting issues;
- lower dashboard-level transformation complexity;
- reduced failed deployments;
- better test coverage for critical datasets;
- shorter analyst onboarding;
- fewer repeated SQL implementations;
- clearer lineage;
- more reliable reconciliation;
- faster delivery of new reporting requirements.
These outcomes connect engineering practices to business value.
20. When does an organization need analytics engineering?
Analytics engineering becomes increasingly valuable when:
- the warehouse contains many transformation scripts;
- multiple dashboards repeat the same logic;
- analysts frequently disagree about definitions;
- changes regularly break downstream reporting;
- the organization has multiple BI developers;
- data models are difficult to understand;
- warehouse transformations lack tests;
- production changes are made manually;
- business reporting depends heavily on SQL;
- the company is scaling its data team.
A very small reporting environment may not need a sophisticated framework immediately.
The practices become more valuable as complexity and consequence grow.
A practical operating model
A simple analytics engineering workflow can look like this:
- Source data lands in the warehouse through ingestion pipelines.
- Staging models standardize source structures.
- Reusable intermediate models apply shared transformations.
- Business marts implement governed analytical logic.
- Automated tests validate structural and business expectations.
- Code changes are reviewed in version control.
- CI validates proposed changes.
- Approved changes deploy to production.
- Critical outputs reconcile to source systems.
- BI and analytical tools consume governed models.
- Failures generate alerts with named owners.
- Documentation and lineage help teams understand dependencies.
dbt can support much of this workflow, but the process and ownership are as important as the tool.
What should business leaders ask before adopting dbt?
Ask the data team:
- Which transformation problems are we trying to solve?
- Where does transformation logic live today?
- How many critical metrics are duplicated across reports?
- Who will own the dbt repository?
- Which models are business critical?
- What tests will protect those models?
- How will code be reviewed?
- How will development and production be separated?
- How will deployments work?
- How will failed tests be handled?
- How will critical metrics reconcile to source systems?
- Who owns metric definitions?
- How will documentation remain current?
- What skills does the team need?
- What measurable improvement should we expect?
If the answers focus only on installing a tool, the organization is not yet designing an analytics engineering operating model.
Frequently asked questions
What is dbt?
dbt is a transformation framework used to build, test, document and manage analytical data models in a data platform. It allows teams to define warehouse transformations as code and apply software-engineering practices to them.
What is analytics engineering?
Analytics engineering is the discipline of creating reliable, reusable, tested and documented analytical datasets. It typically sits between raw data engineering and downstream analysis or BI.
Does dbt replace ETL tools?
Usually not. In an ELT architecture, ingestion tools load source data into the warehouse and dbt transforms it there. The exact architecture depends on the source and platform.
Does dbt replace Power BI, Tableau or Looker?
No. BI tools remain the presentation and analytical experience for users. dbt helps prepare governed datasets that those tools can consume.
Does dbt create a single source of truth?
Not by itself. It can centralize and test analytical logic, but the business must still agree on definitions, ownership and governance.
Is dbt only for large companies?
No, but the value increases with transformation complexity. Small teams can benefit from version control and testing, while larger environments gain more from lineage, standards and deployment discipline.
Does every transformation belong in dbt?
No. Source-specific ingestion transformations, streaming logic, application processing and presentation-specific calculations may belong elsewhere. The architecture should place logic where it can be governed and operated effectively.
What is the biggest organizational change when adopting dbt?
Teams need to stop treating analytical SQL as disposable queries and start treating important transformations as maintained production assets.
The real value is disciplined analytical change
dbt is useful because it gives analytics teams a framework for working more like engineering teams.
But the deeper change is organizational.
Critical business logic becomes versioned.
Changes become reviewable.
Models become testable.
Dependencies become visible.
Definitions become reusable.
Production deployments become controlled.
That makes the warehouse easier to trust and easier to change.
If your organization is building a modern warehouse or trying to bring discipline to a growing transformation layer, Actiknow can help design the data architecture, transformation workflow, testing approach and BI consumption model. Contact Actiknow to discuss where analytics engineering should fit in your data platform.